fal.ai is a strong platform for AI image and video generation, but is it worth the price in 2026? Its extensive model catalog, asynchronous APIs, and Serverless GPU capabilities appeal to developers. However, model-specific pricing and concurrency limits make it essential to evaluate the real cost of running AI applications at scale.
Small price differences can become thousands of dollars in production. For Gemini 3.1 Flash Image at 1K resolution, fal.ai lists $0.08 per image, versus $0.05025 on LinkModel—approximately 37.2% less. At 100,000 images, that translates to $2,975 in potential savings before retries and other costs. And as this fal.ai pricing breakdown shows, GPU utilization, billing units, and failed requests can further complicate the comparison.
Why pay more for a supported model without comparing your options? LinkModel offers pay-as-you-go API pricing, with savings of up to 30% versus official API rates on eligible models, plus unified access to supported image, video, and language models. For cost-conscious developers, lower published generation prices and one API for multiple model families make LinkModel a compelling alternative. Compare LinkModel's prices and test the endpoints that fit your workload before committing.
fal.ai Review 2026: Quick Verdict
fal.ai is worth considering when model selection, creative workflows, and deployment flexibility matter more than minimizing the price of every individual request. Developers who primarily use a few commercial models should compare those endpoints against alternatives before committing.
| Evaluation area | Verdict | What developers should know |
|---|---|---|
| Model selection | Strong | Broad image, video, and other generative AI endpoint coverage |
| Developer experience | Strong | Model schemas, API examples, playgrounds, and asynchronous jobs |
| Model API pricing | Depends on model | Different endpoints use different billing units |
| Custom GPU deployment | Strong fit for specialized workloads | Serverless runner-lifetime billing requires cost management |
| Production scalability | Requires planning | Account and endpoint concurrency limits can affect throughput |
| Asset handling | Requires attention | Output retention and access permissions must be reviewed |
| Commercial-model value | Mixed | Some comparable models are cheaper through alternative providers |
| Best overall use case | Creative AI development | Especially valuable when fal-specific endpoints or tooling are required |
Who should use fal.ai?
fal.ai is particularly suitable for:
- AI image and video applications that need access to multiple model families.
- Developers experimenting with creative models before selecting a production endpoint.
- Teams building asynchronous media-generation pipelines.
- Organizations that need custom inference code running on GPU infrastructure.
- Applications where endpoint-specific functionality matters more than the lowest advertised request price.
Who should compare alternatives first?
Consider other providers when your application depends on a small number of commercially available models, your main goal is reducing generation cost, or you want a unified API for text, image, and video without operating custom GPU workloads.
The important distinction is that fal.ai can be an excellent development platform without being the lowest-cost provider for every model.
What Is fal.ai, and How Does It Work?
fal.ai is a developer platform for running generative AI workloads through hosted model endpoints and GPU-backed infrastructure.
Its two major product paths solve different problems:
| Product | What you manage | How pricing works | Best for |
|---|---|---|---|
| fal Model APIs | Requests, parameters, and generated outputs | Endpoint-specific units such as images, video seconds, requests, or tokens | Applications using hosted models |
| fal Serverless | Custom inference code, deployment configuration, and scaling behavior | GPU runner lifetime and machine rate | Custom models and specialized inference |
This distinction matters because a hosted image-generation request and a custom GPU deployment do not have equivalent cost structures.
With Model APIs, developers generally pay according to the endpoint's published billing unit. With Serverless, costs depend on how long provisioned runners remain alive, including certain periods when they are not actively processing requests.
A fair comparison must therefore match the product category: hosted API against hosted API, or custom deployment against equivalent compute infrastructure.
For a breakdown of these different billing models, see the fal.ai pricing guide.
How to Use the fal.ai API: A Practical Example
The fastest way to evaluate fal.ai is to select a specific endpoint, inspect its input schema, and submit a small request before building a larger application.
Model pages provide the parameters and code examples required for integration. Long-running generation jobs can use asynchronous submission rather than keeping an HTTP connection open.
Step 1: Create an API key
Create an account, obtain an API key, and store it as an environment variable.
pip install fal-clientOn macOS or Linux:
export FAL_KEY="YOUR_FAL_API_KEY"For Windows PowerShell:
$env:FAL_KEY="YOUR_FAL_API_KEY"Avoid placing API keys directly in frontend applications, public repositories, or client-side source code.
Step 2: Submit an image-to-video request
The following Python example uses fal's published Seedance 2.0 image-to-video endpoint.
import fal_client

result = fal_client.subscribe( \
"bytedance/seedance-2.0/image-to-video", \
arguments={ \
"prompt": ( \
"A cinematic slow camera push toward " \
"a mountain landscape at sunrise." \
), \
"image_url": "https://your-domain.com/input.jpg", \
"resolution": "720p", \
"duration": "5", \
"generate_audio": True, \
}, \
)

print(result["video"]["url"])
Replace the example image URL with a valid publicly accessible image or another supported input location.
The exact parameters, accepted duration values, and model identifier should always be checked against the current endpoint schema.
Step 3: Use asynchronous processing for longer jobs
Video generation can take substantially longer than a typical text API request.
For production applications, fal supports a queue-oriented workflow:
handler = fal_client.submit( \
"bytedance/seedance-2.0/image-to-video", \
arguments={ \
"prompt": "A cinematic landscape at sunrise.", \
"image_url": "https://your-domain.com/input.jpg", \
"resolution": "720p", \
"duration": "5", \
}, \
)

request_id = handler.request_id \
print(request_id)

result = handler.get() \
print(result["video"]["url"])
This is an illustrative integration example based on the documented client interface, not a record of an executed benchmark.
Step 4: Record production metrics
A reliable application should record more than whether the request succeeded.
Capture the request ID, endpoint identifier, request parameters, submission time, queue duration where available, completion status, output metadata, and billed cost.
Store generated media in infrastructure you control when long-term availability or access restrictions are required.
The key lesson: A successful playground request demonstrates basic compatibility, not production readiness.
How Much Does fal.ai Cost in 2026?
fal.ai Model API pricing depends on the endpoint and output configuration. There is no universal per-request or GPU-second price across its hosted model catalog.
Its official pricing page lists model-specific rates, while individual endpoint pages explain additional conditions such as resolution, duration, or output quality.
Typical billing units include:
- Price per generated image.
- Price per image megapixel.
- Price per generated video second.
- Price per request or completed video.
- Price per token for supported models.
- Compute-based billing where an endpoint does not have a fixed output rate.
This flexibility allows different models to use billing units suited to their workloads. It also makes comparing providers more complicated.
fal.ai vs LinkModel: Gemini 3.1 Flash Image pricing
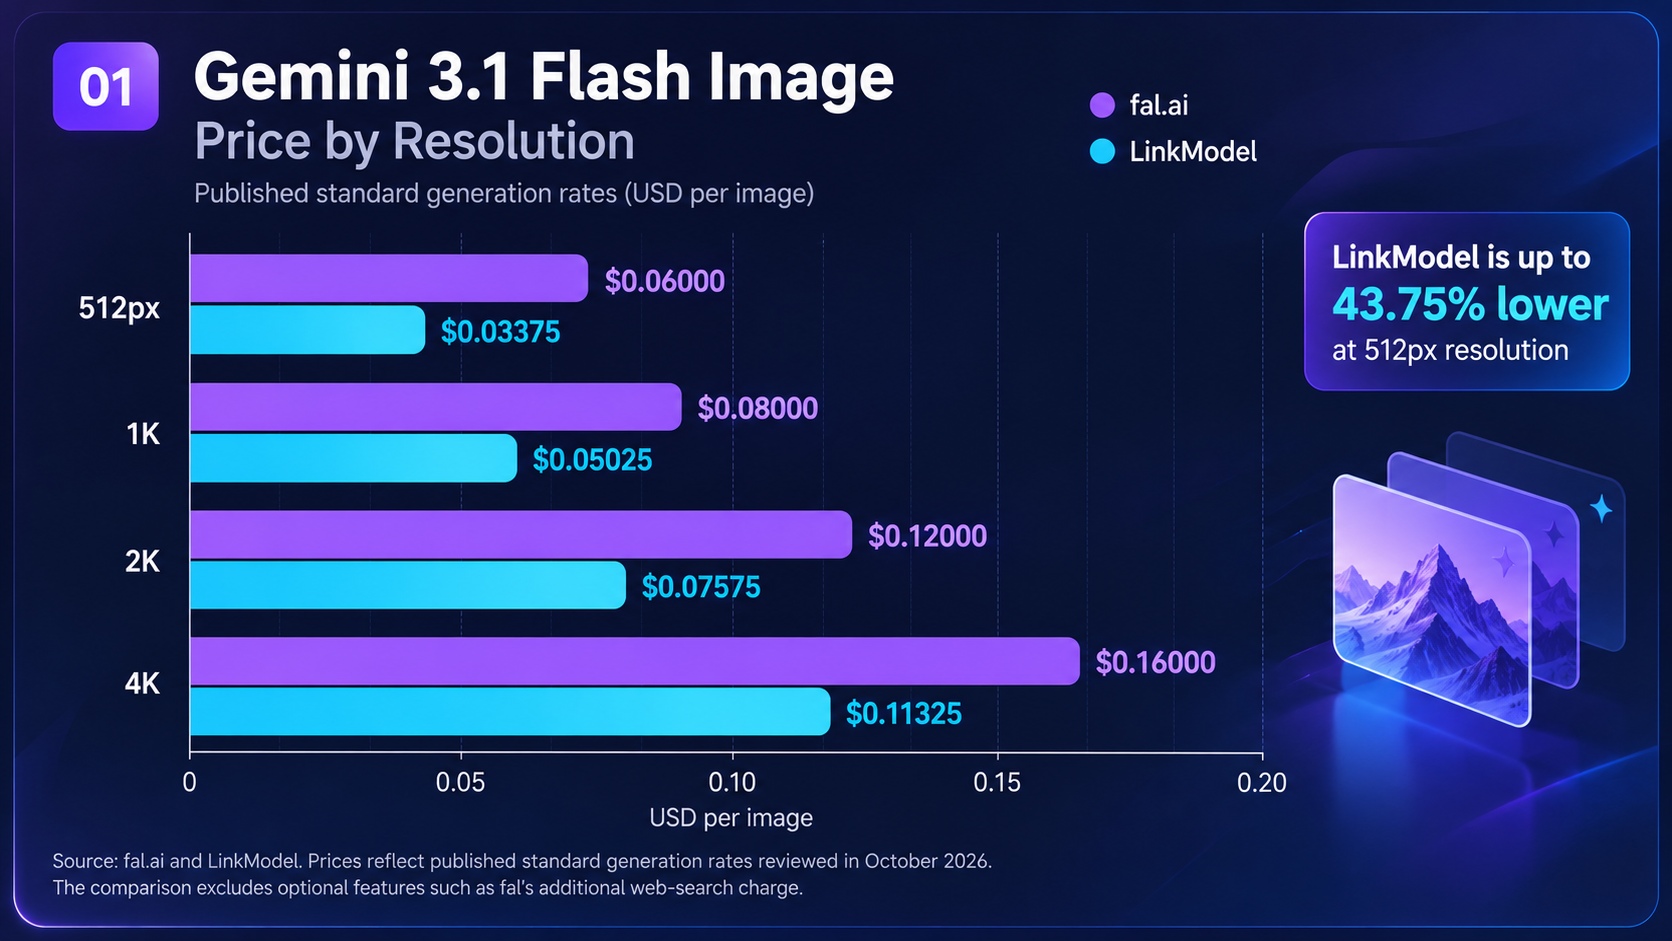
Gemini 3.1 Flash Image provides a useful comparison because both platforms publish prices for the same model family and output resolution.
| Resolution | fal.ai per image | LinkModel per image | Difference |
|---|---|---|---|
| 512px tier | $0.06000 | $0.03375 | 43.75% lower |
| 1K | $0.08000 | $0.05025 | 37.19% lower |
| 2K | $0.12000 | $0.07575 | 36.88% lower |
| 4K | $0.16000 | $0.11325 | 29.22% lower |
Sources: fal Gemini 3.1 Flash Image and LinkModel Gemini 3.1 Flash Image. Prices reflect published standard generation rates reviewed in October 2026.
The comparison excludes optional features such as fal's additional web-search charge. Model versions, preview versus stable identifiers, feature availability, and output requirements must be checked before treating these prices as fully interchangeable.
For applications generating large volumes of 1K images, the difference becomes more meaningful.
| Monthly successful 1K images | fal.ai | LinkModel | Listed cost difference |
|---|---|---|---|
| 100 | $8.00 | $5.03 | $2.98 |
| 1,000 | $80.00 | $50.25 | $29.75 |
| 10,000 | $800.00 | $502.50 | $297.50 |
| 100,000 | $8,000.00 | $5,025.00 | $2,975.00 |
These are mathematical projections using published per-image rates, not actual customer invoices. They assume one billable generation per image and exclude retries, optional features, discounts, and other operating expenses.
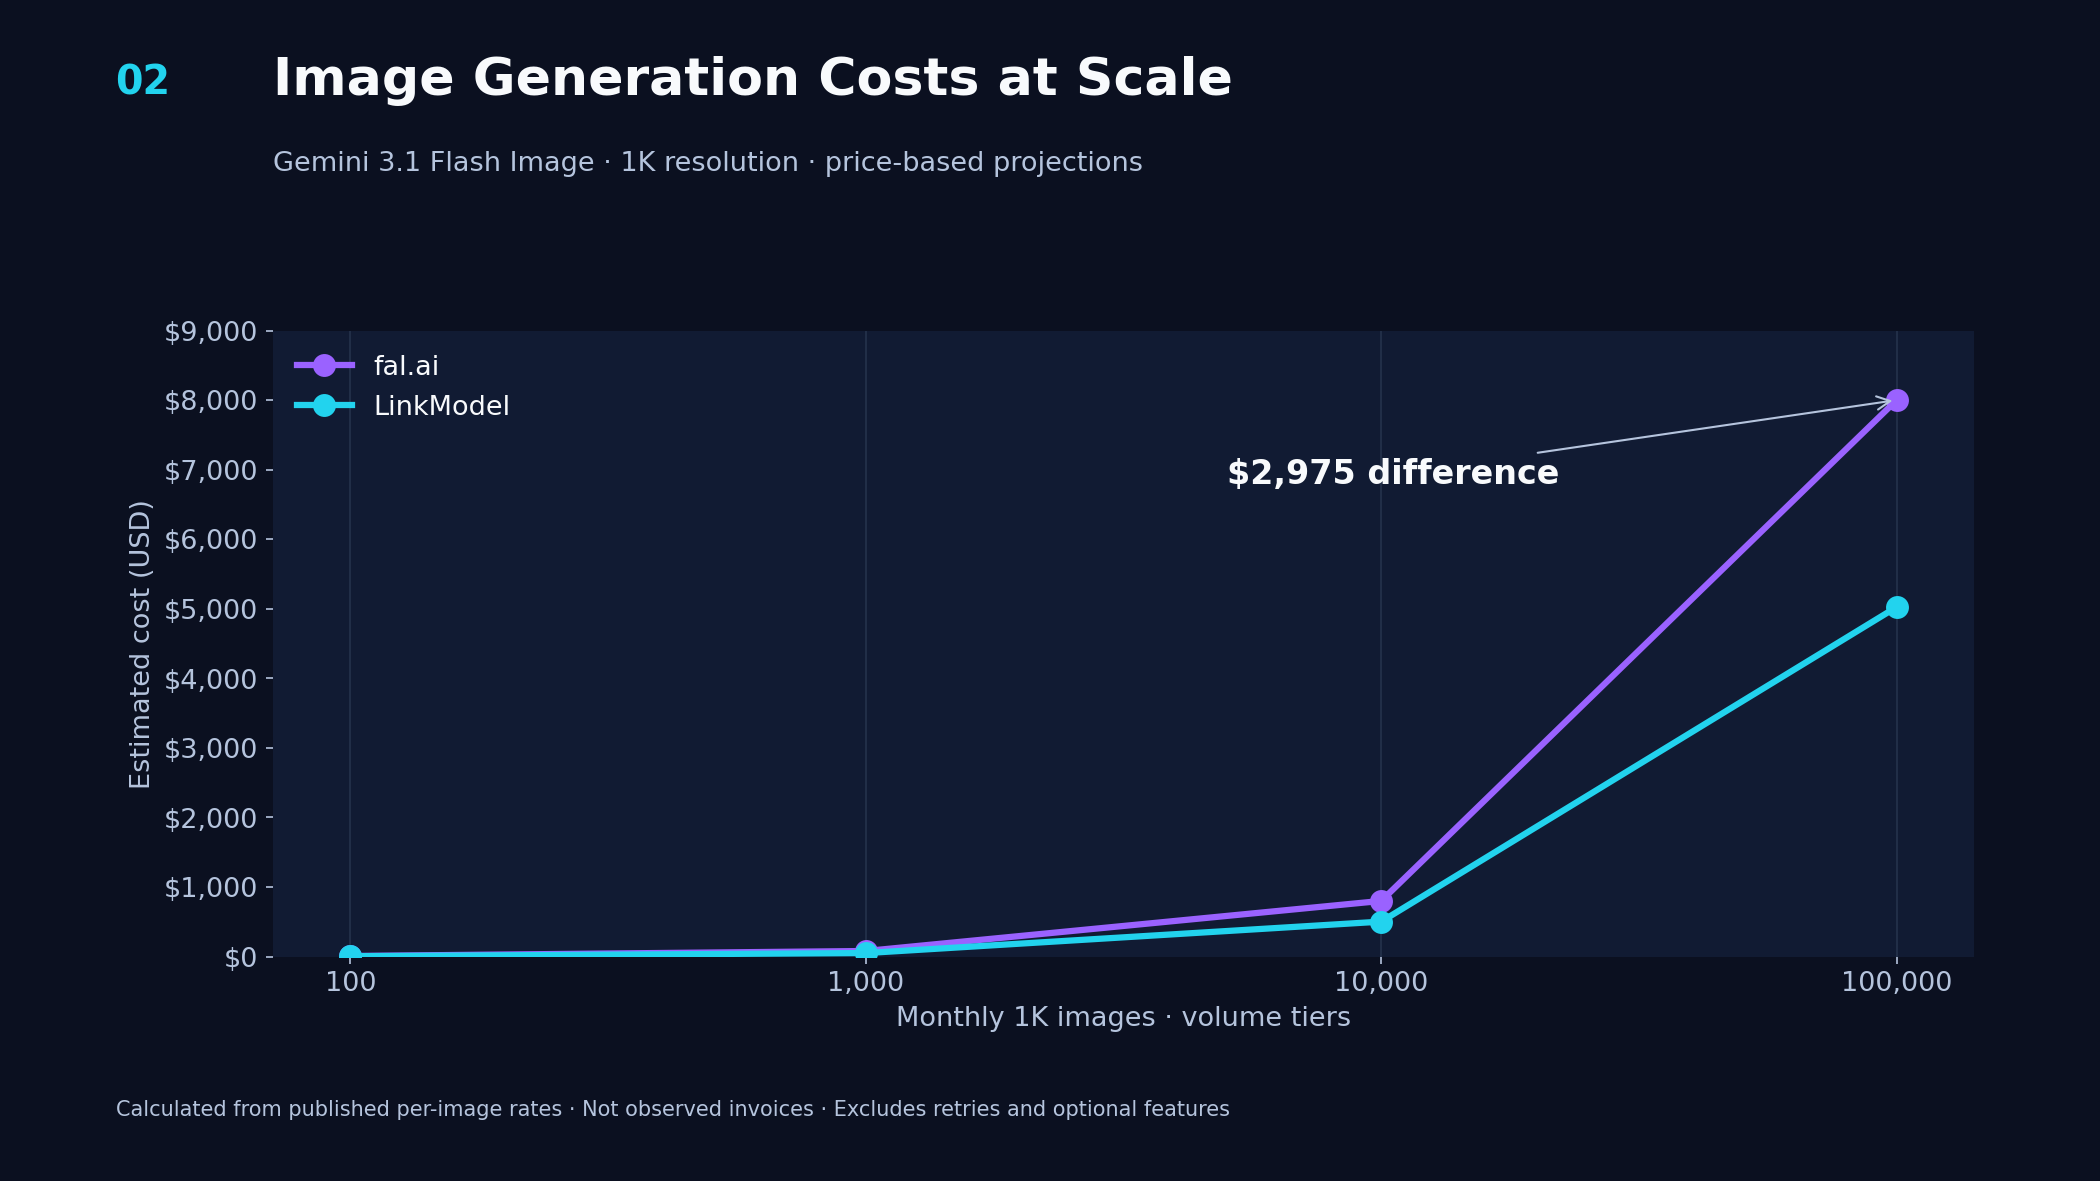
At 10,000 images per month, LinkModel's listed rate would reduce generation spending by $297.50 under those assumptions.
That is a meaningful reason to compare providers, but not sufficient evidence that either provider produces better images or delivers lower latency.
Seedance 2.0 pricing: Why billing units matter
Seedance 2.0 demonstrates why comparing AI video pricing requires more care.
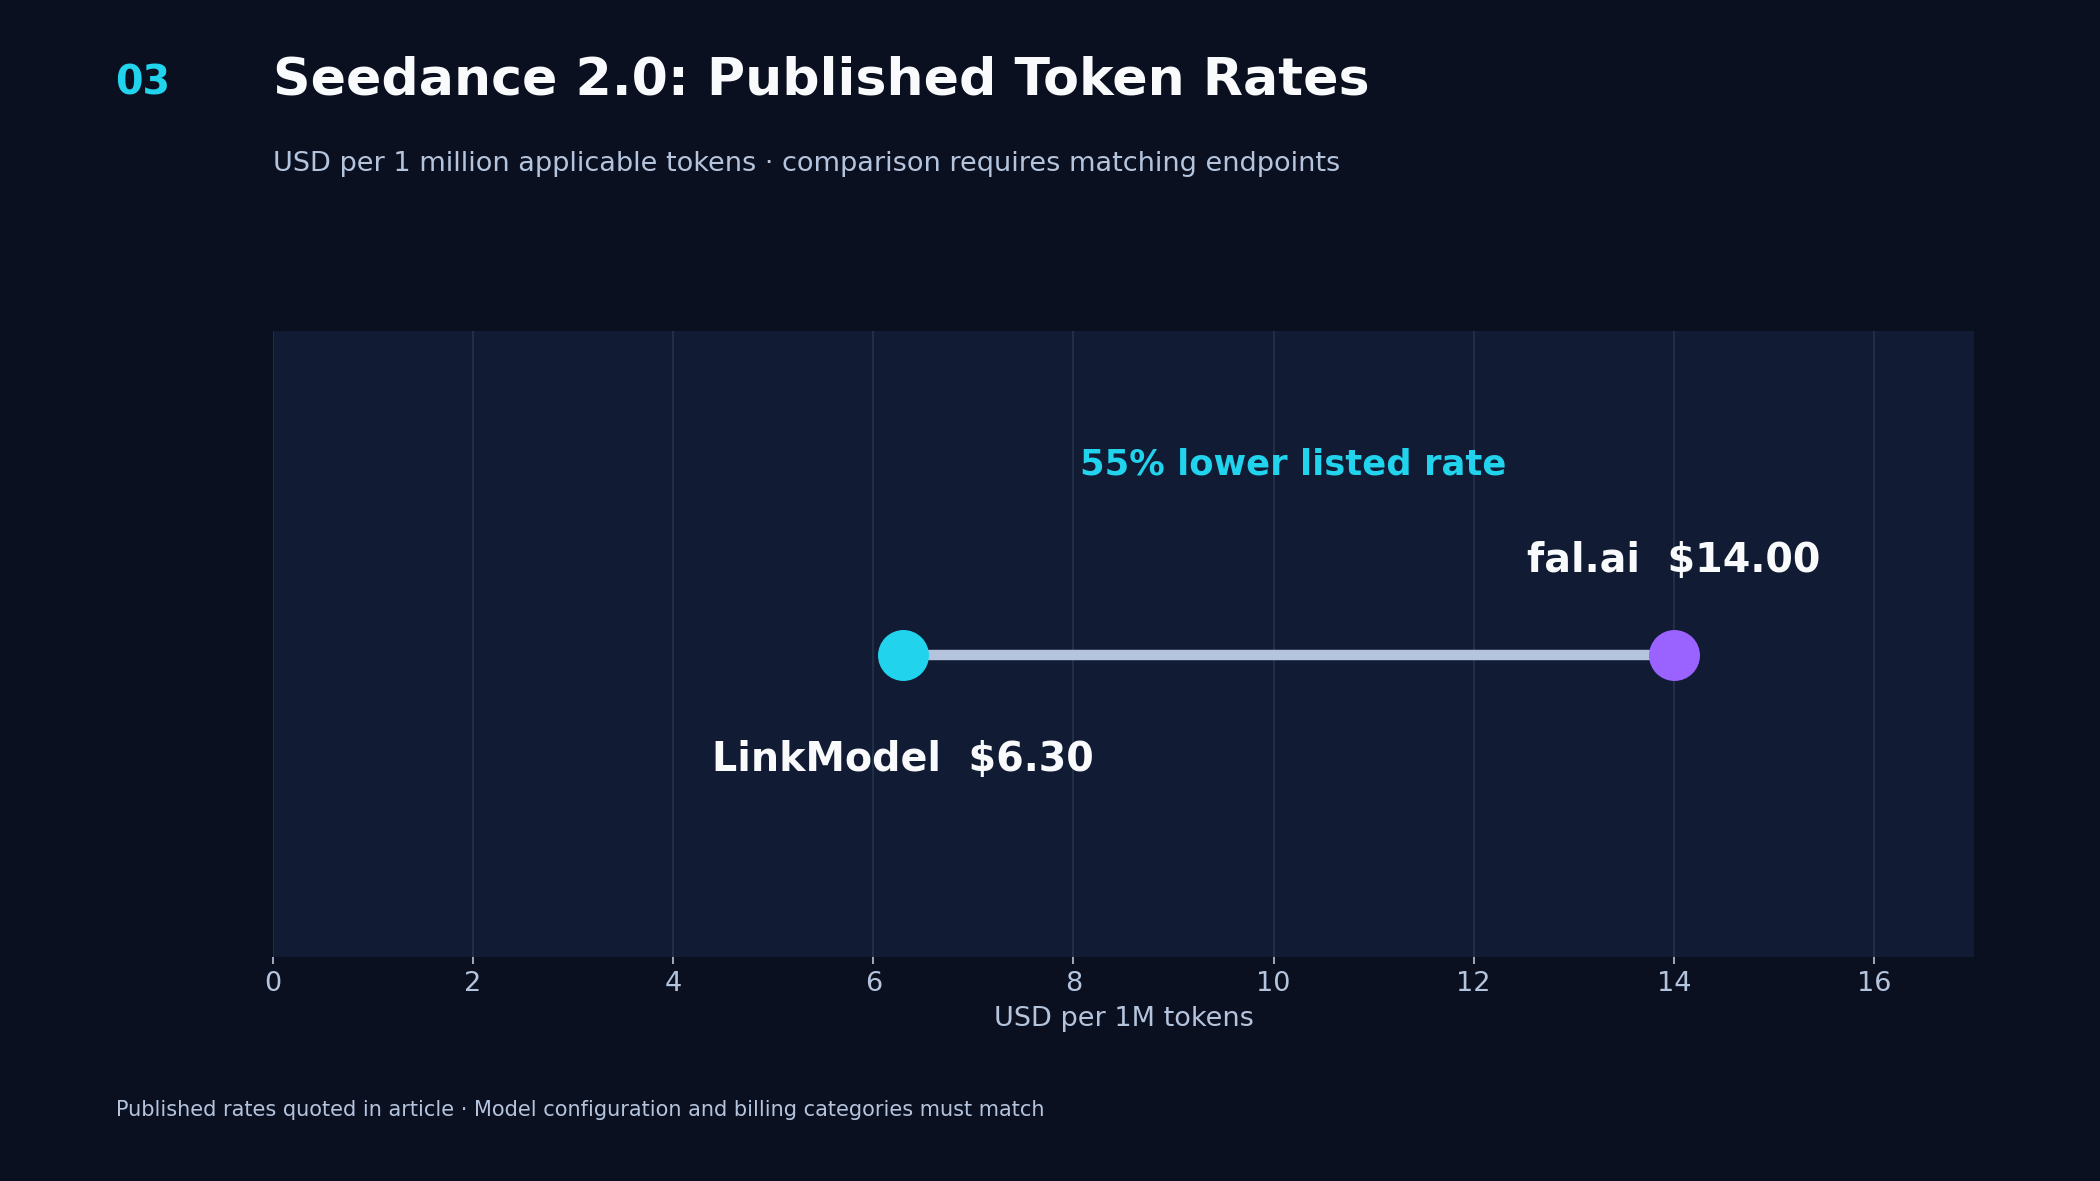
fal's standard 720p image-to-video endpoint lists a token rate of $0.014 per 1,000 tokens and a published video-second price around $0.3024, although the endpoint interface also displays an approximately $0.3034 estimate.
LinkModel lists $6.30 per million output tokens for the relevant 720p configuration without video-reference input.
| Billing comparison | fal.ai | LinkModel |
|---|---|---|
| Published rate per 1M applicable tokens | $14.00 | $6.30 |
| Rate difference | Baseline | 55% lower |
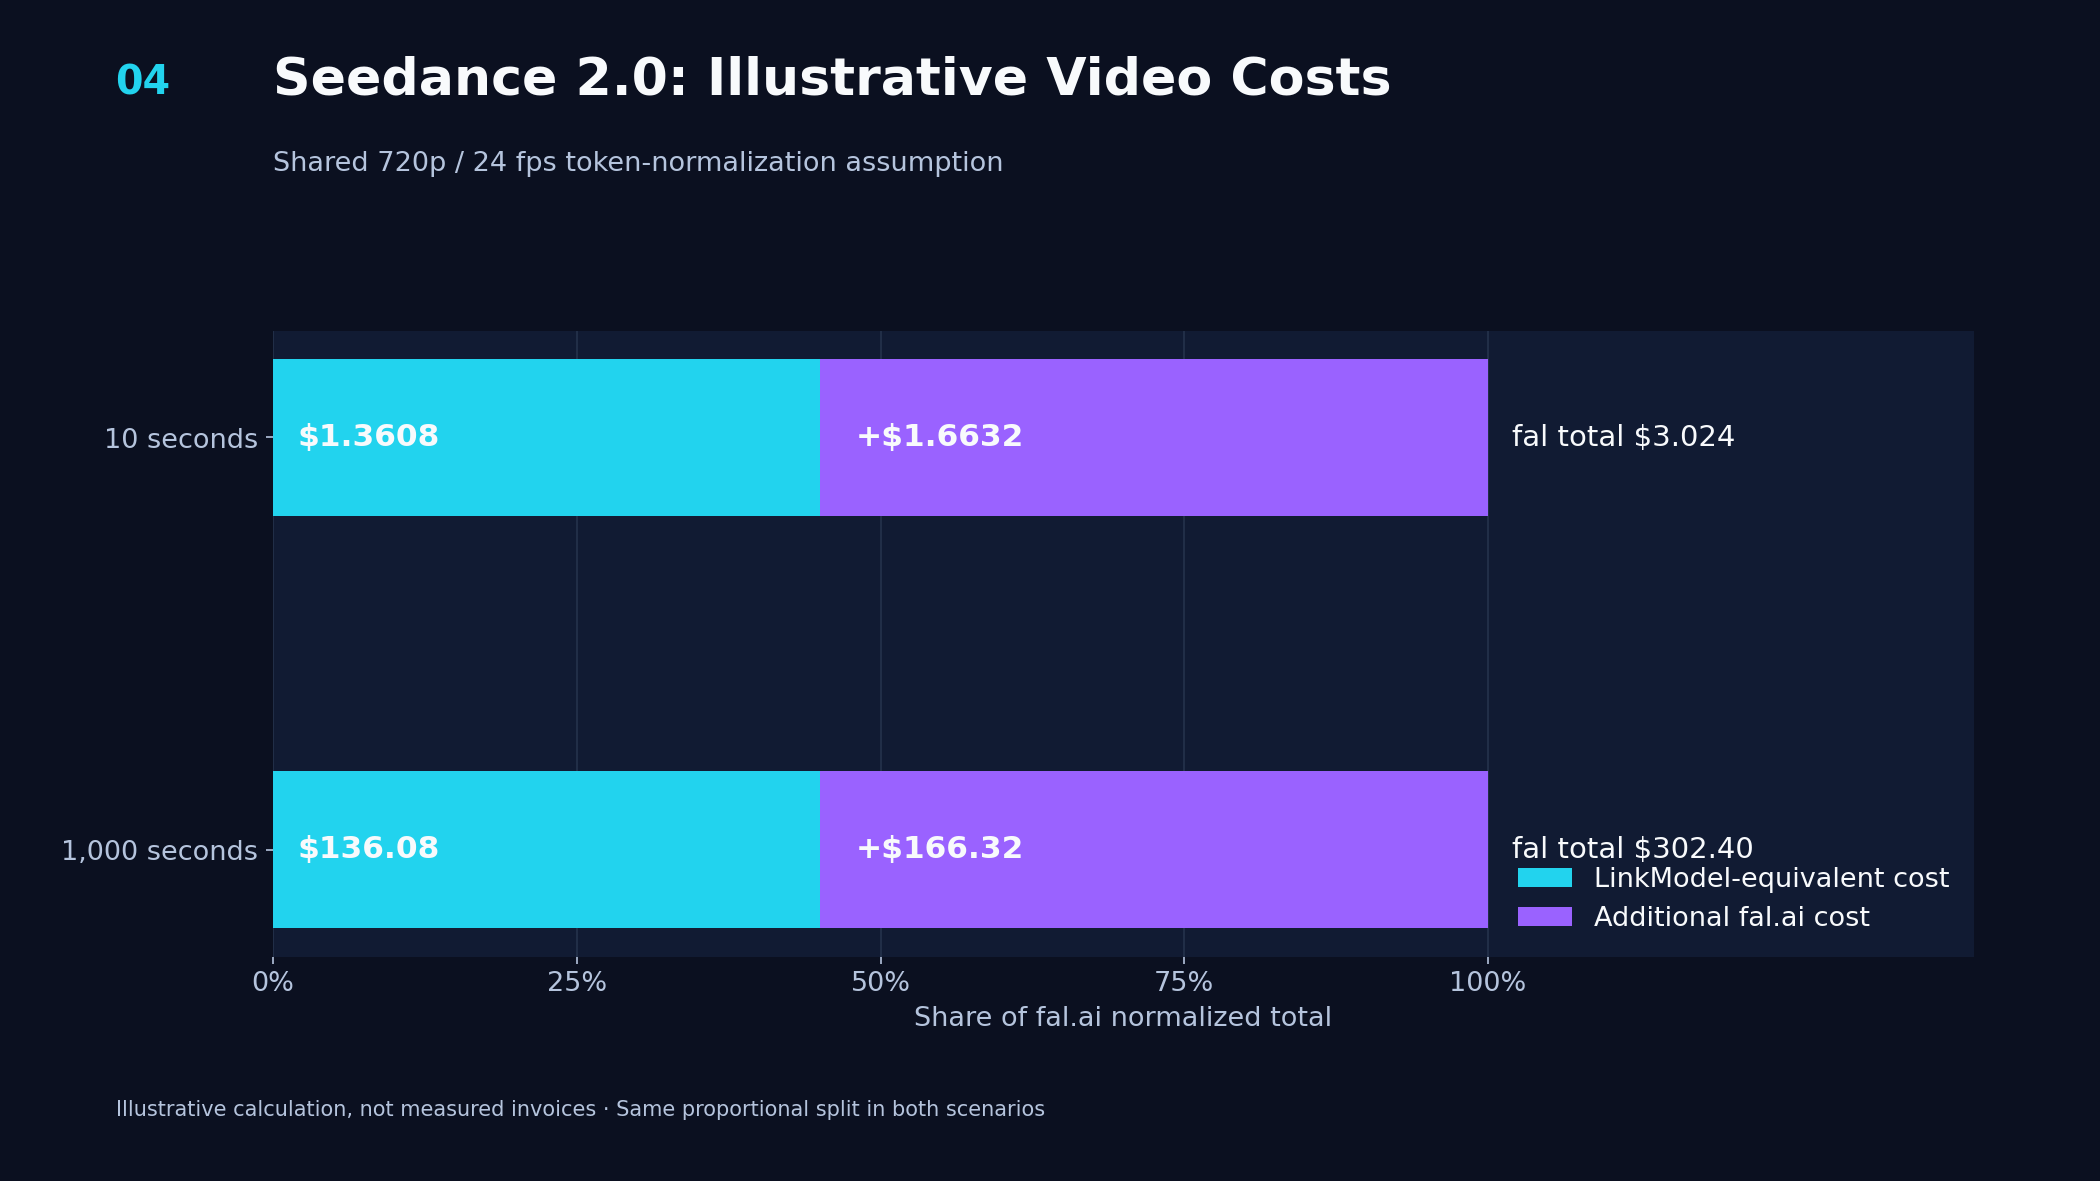
| 10-second 720p output, illustrative normalization | $3.024 | $1.3608 |
| 1,000 seconds, illustrative normalization | $302.40 | $136.08 |
The normalization assumes 1280 × 720 output at 24 fps and applies:
Video tokens = width × height × duration × 24 ÷ 1024
For a 10-second clip:
1280 × 720 × 10 × 24 ÷ 1024 = 216,000 tokens
At $14 per million tokens, the calculated cost is $3.024. At $6.30 per million tokens, it is $1.3608.
Important comparison limitation: These figures compare published rates under a shared mathematical token assumption. They do not prove identical endpoint behavior, audio handling, model revision, generation quality, or final billing across providers. The fal interface's approximate per-second display also differs slightly from its tabulated normalized rate.
Source pages: fal Seedance 2.0 and LinkModel Seedance 2.0.
Before switching providers, confirm that the exact input configuration and desired output are supported on both.
Why the cheapest request is not always the cheapest result
A lower listed rate does not automatically mean lower production cost.
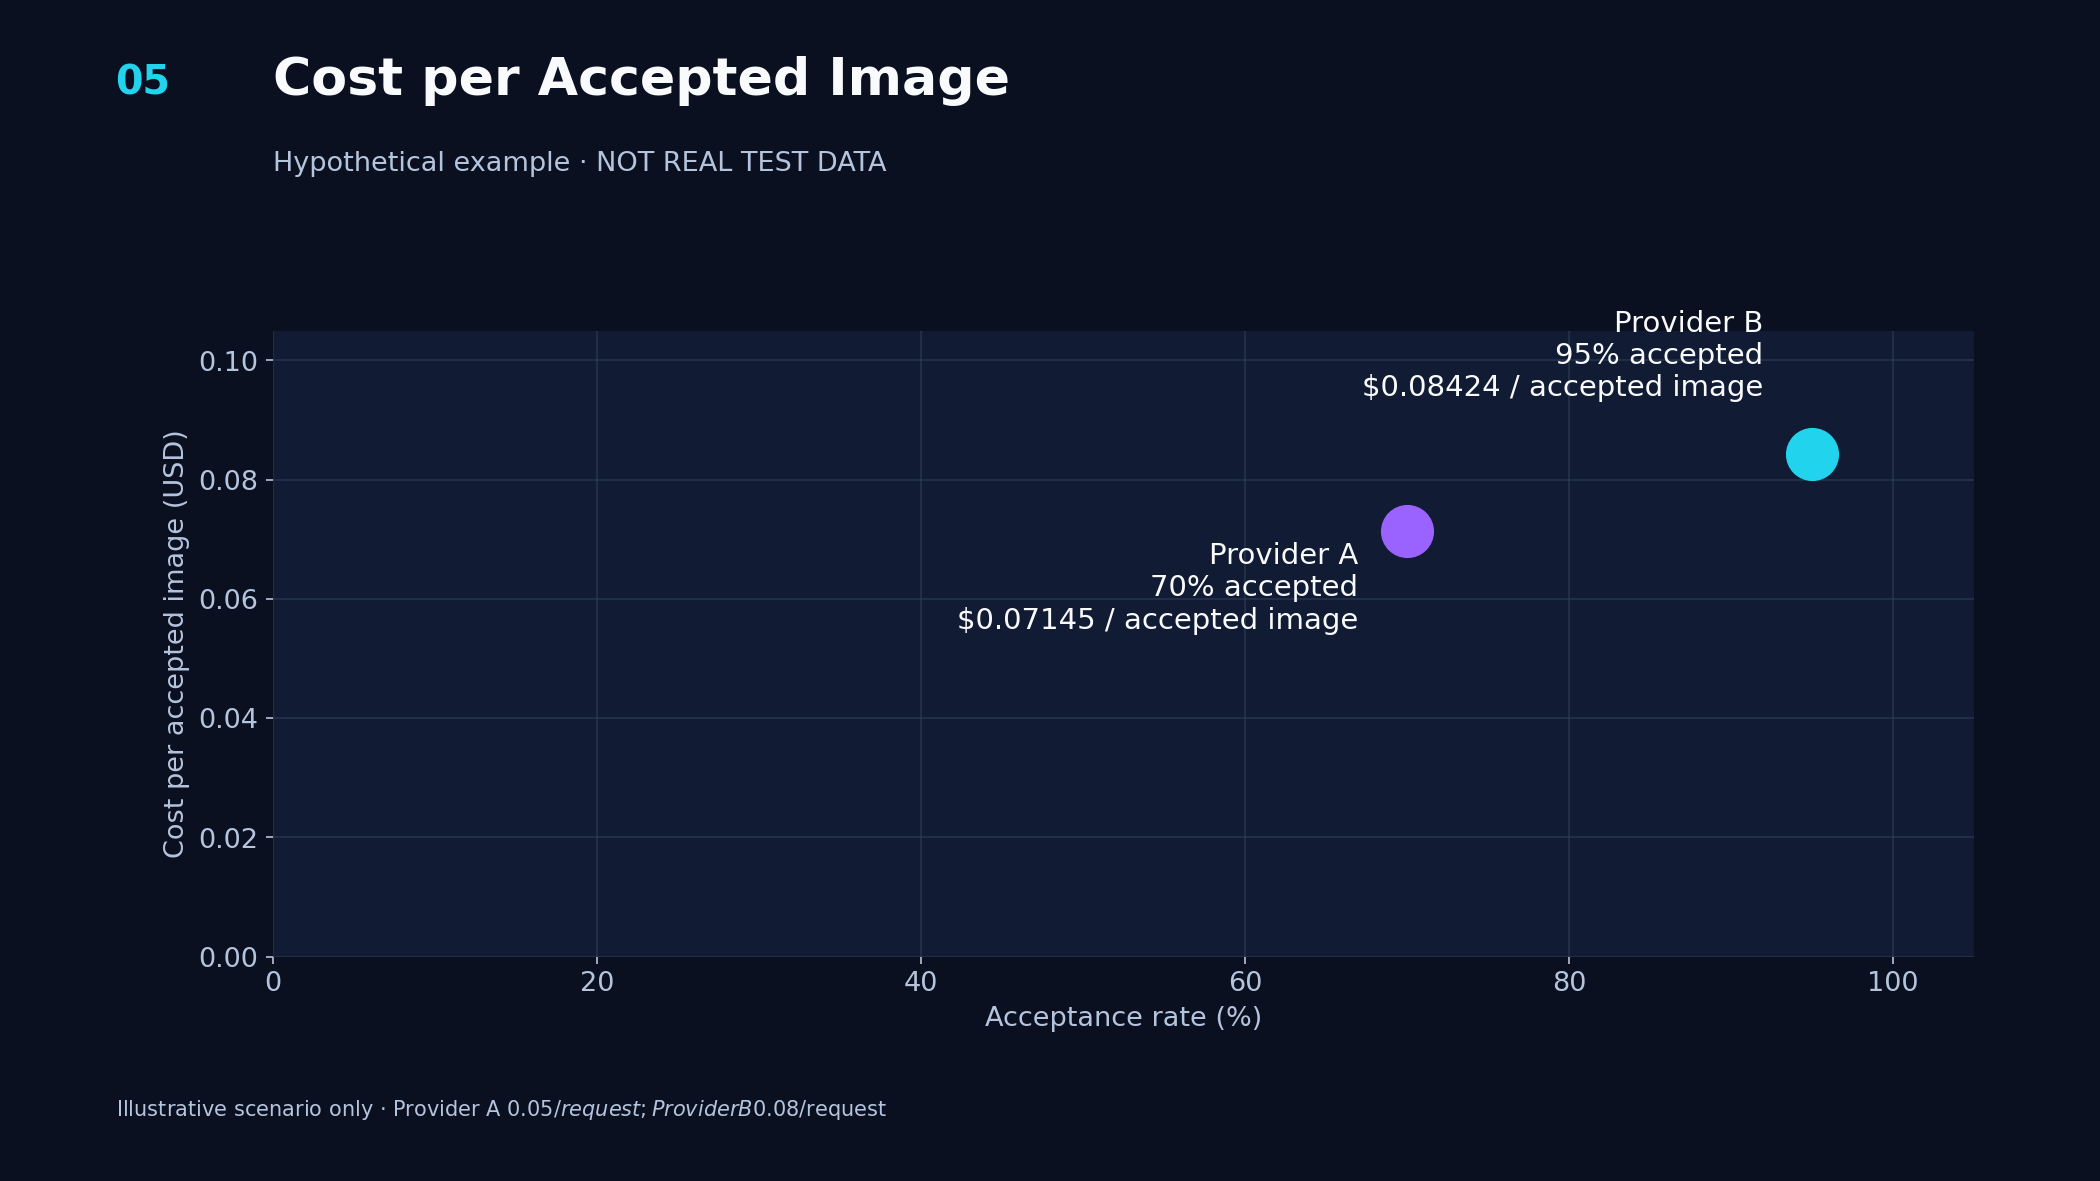
Consider an illustrative application that needs 1,000 accepted images.
| Metric | Provider A | Provider B |
|---|---|---|
| Price per generation | $0.05 | $0.08 |
| Acceptance rate | 70% | 95% |
| Estimated generations required | 1,429 | 1,053 |
| Estimated generation cost | $71.45 | $84.24 |
| Cost per accepted image | $0.07145 | $0.08424 |
In this hypothetical example, Provider A remains cheaper despite its lower acceptance rate. But if its acceptance rate fell further, that advantage could disappear.
Use the formula:
Cost per accepted output = Total billable generation cost ÷ Number of accepted outputs
For commercial image and video workflows, this metric is often more useful than the price of a single request.
fal.ai Concurrency, Queue Time, and Production Scaling
fal.ai supports asynchronous generation and request queues, but throughput depends on account limits, endpoint capacity, and the time required to complete each job.
A request being accepted into a queue does not mean it has started inference.
Developers should distinguish:
| Metric | What it measures | Why it matters |
|---|---|---|
| Queue time | Time before processing starts | User waiting experience |
| Inference time | Time spent executing the model | Generation performance |
| End-to-end latency | Submission to completed result | Product responsiveness |
| Concurrency | Jobs permitted to run simultaneously | Throughput |
| Success rate | Completed requests relative to attempts | Reliability |
| Accepted-output rate | Outputs passing application quality checks | Actual business value |
fal's documented Model API concurrency scheme has described a starting allowance of two concurrent requests for new accounts, with higher limits tied to recent paid usage and account arrangements.
These limits should be reconfirmed against the current documentation and your account before launch. Model-specific restrictions may also apply.
How concurrency affects throughput
Suppose a model takes an average of 30 seconds to complete a generation.
With two simultaneous active requests, the theoretical maximum is:
2 × 60 ÷ 30 = 4 completed jobs per minute
This is only a simplified capacity calculation. Real throughput may be lower because of variable processing time, scheduling, queueing, errors, and endpoint restrictions.
A production team should measure throughput at expected peak traffic rather than assume the account-level concurrency number translates directly into guaranteed capacity.
How to evaluate fal.ai latency
A useful test should submit identical workloads under controlled conditions and report:
- Median end-to-end latency.
- 95th-percentile end-to-end latency.
- Median queue time.
- Completion and error rates.
- Throughput at different concurrency levels.
- Total billed cost.
For a provider comparison, use the same model revision and generation settings wherever possible.
Without these measurements, claims such as "fal.ai is faster" or "another provider is more reliable" remain unproven.
fal.ai Credits, Failed Requests, and Hidden Billing Risks
The most important billing risks are not necessarily hidden fees. They are the operational details that can make actual spending differ from a simple price estimate.
Are failed requests charged?
fal's published billing guidance distinguishes server-side failures from certain client-side errors.
Server-side HTTP 5xx failures are generally described as non-billable. However, some client errors can potentially incur charges when GPU work has already started before the problem is detected.
For expensive generation endpoints, developers should validate inputs before submission rather than rely entirely on the provider to reject invalid requests without cost.
Record the request ID, error category, billing result, and whether processing began.
Do fal.ai credits expire?
fal has published a 365-day expiration period for purchased credits. Before buying a large balance, confirm the current terms applicable to your account, purchase date, and any promotional credits.
The operational question is not simply whether credits expire, but whether your forecast consumption is high enough to use them before expiration.
Are queue time and cold starts charged?
For hosted Model APIs, fal's documentation distinguishes output billing from infrastructure time. Queue waiting and Model API cold starts are not generally charged as separate GPU-time items.
Custom Serverless deployments are different because runner-lifetime billing can include idle and setup states.
Do not apply Model API billing rules to custom GPU deployments.
What budget controls should developers implement?
At minimum, production applications should have input validation, request logging, cost tracking, controlled retries, and internal spending alerts.
For expensive video endpoints, calculate a maximum expected request cost before submission and reject unsupported or unusually costly configurations.
Also verify whether the provider offers the account-level hard spending limits your application requires. Internal alerts alone do not guarantee that spending will stop.
fal GPU Pricing: When Is Custom Serverless Worth It?
fal Serverless is intended for workloads that need custom code or infrastructure behavior beyond a predefined hosted model endpoint.
Its billing model differs fundamentally from Model APIs.
According to fal's Serverless documentation, billable runner lifetime can include setup, idle periods, active processing, draining, and teardown.
The cost depends on the machine type, runner lifetime, and GPU configuration.
How to estimate custom GPU costs
A simplified cost model is:
GPU cost = Billable runner hours × Hourly machine rate × GPU count
For example, consider a hypothetical deployment with a $3-per-GPU-hour rate, one GPU, and 100 billable runner hours.
The compute cost would be:
100 × $3 × 1 = $300
This is an illustration, not a quoted fal GPU price.
The effective cost per output then depends on how many successful outputs the deployment produces during those billable hours.
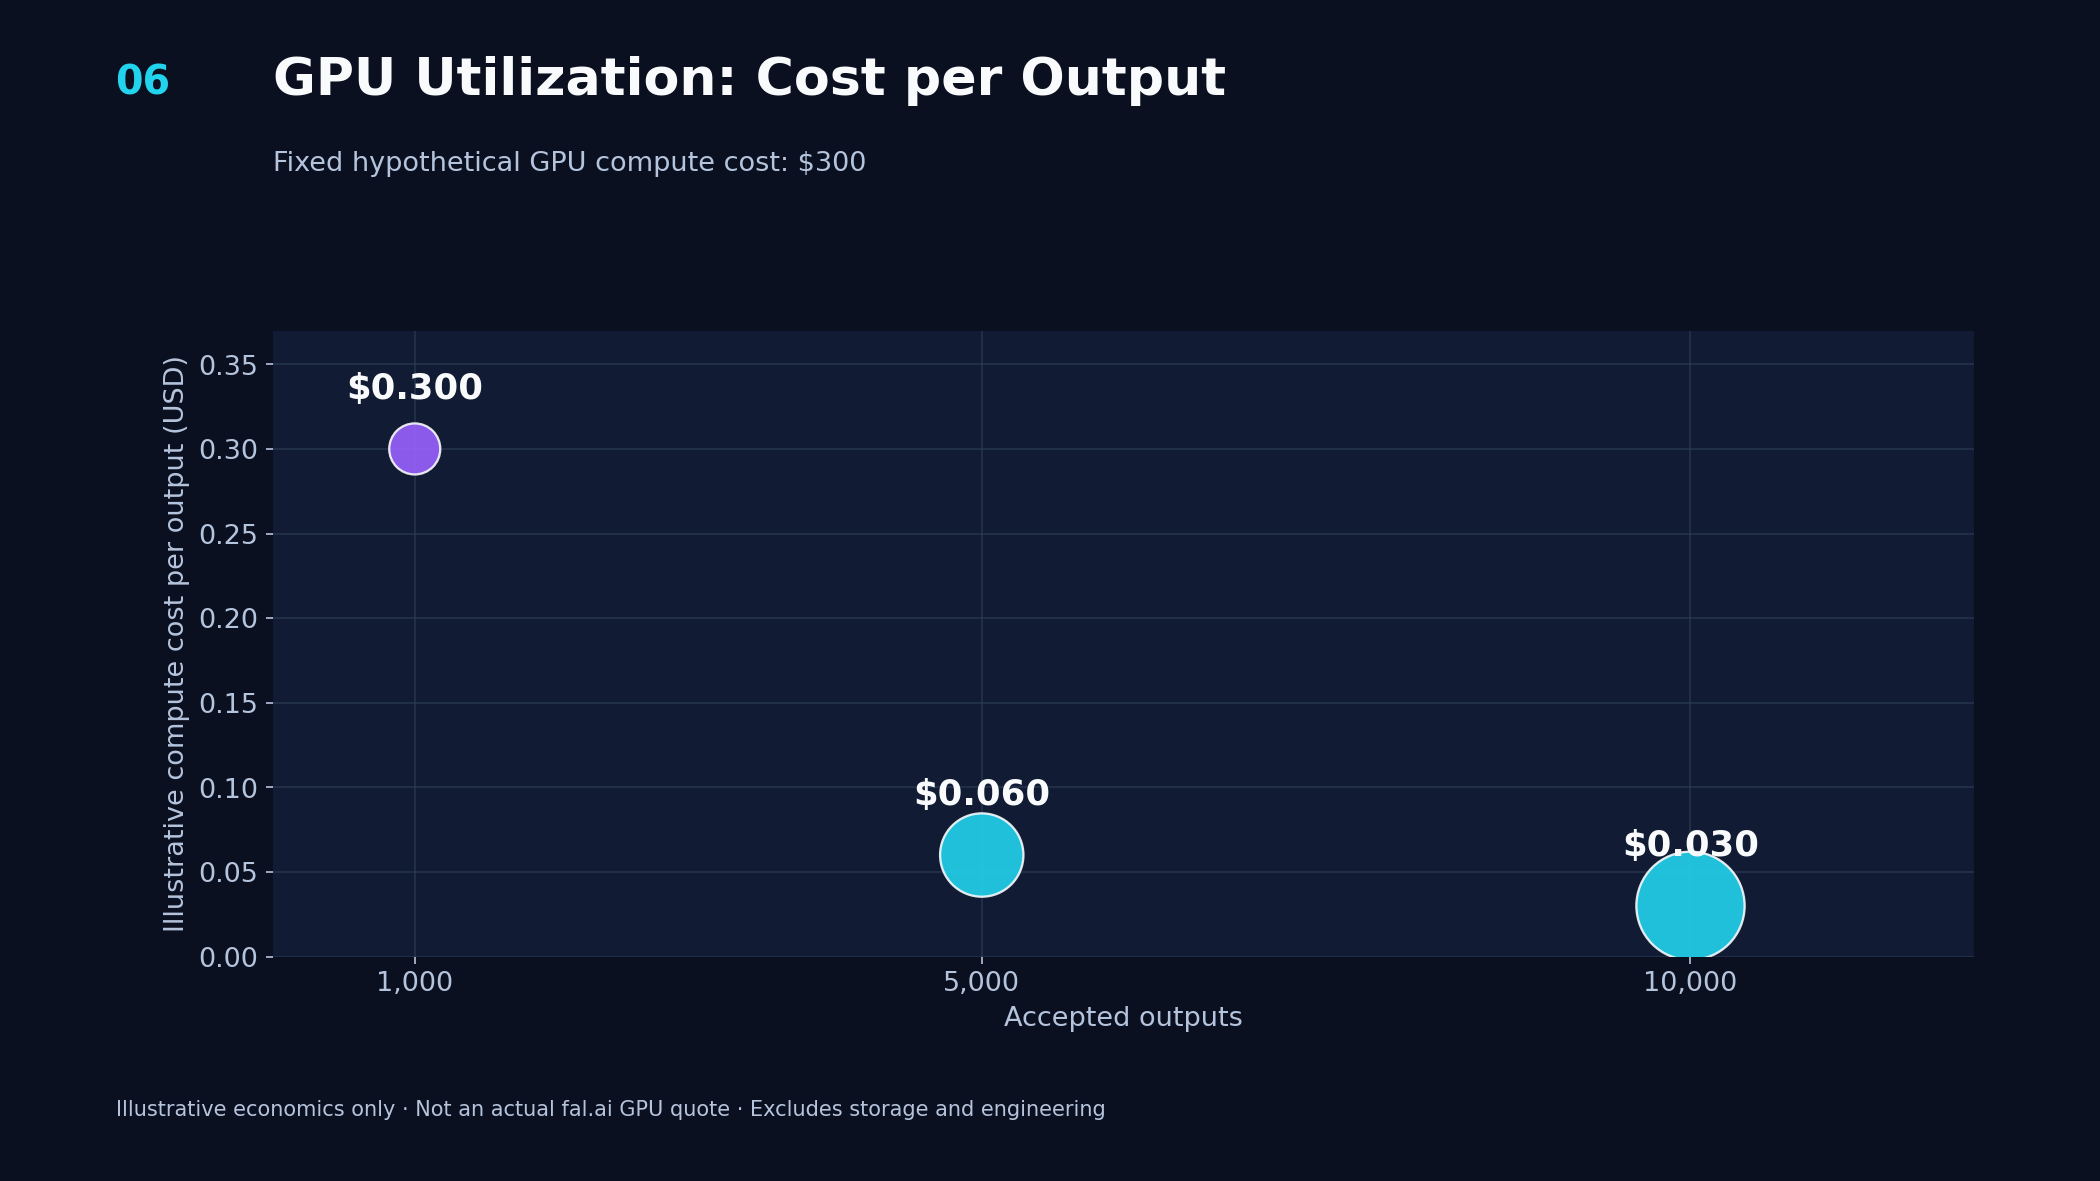
| Monthly accepted outputs | Illustrative $300 compute cost per output |
|---|---|
| 1,000 | $0.300 |
| 5,000 | $0.060 |
| 10,000 | $0.030 |
The calculation excludes storage, networking, engineering time, failed work, and other applicable charges.
It demonstrates why utilization matters: a custom deployment may become economical at high throughput, but an idle GPU runner can erase the expected savings.
When should you choose fal Serverless?
Custom Serverless becomes more attractive when you need:
- Proprietary or modified inference code.
- Custom preprocessing or postprocessing.
- A model unavailable through hosted endpoints.
- Fine-grained runtime configuration.
- A predictable workload that can maintain good GPU utilization.
For teams using existing commercial image or video models, hosted Model APIs are generally the simpler starting point.
The right decision depends on total infrastructure cost, engineering overhead, reliability requirements, and model availability—not GPU hourly price alone.
How Does fal.ai Handle Generated Images and Videos?
Generated media should be treated as application data that requires its own retention, access-control, and storage policy.
fal's published guidance has described generated media availability of at least seven days, with generated URLs publicly accessible by default unless appropriate access controls are configured.
These policies should be checked against the current storage documentation and endpoint configuration.
A publicly accessible URL does not necessarily mean the asset is indexed by search engines. It means that anyone who obtains the URL may be able to retrieve the content, depending on the configured permissions.
Recommended production workflow
After generation, an application should retrieve the output, validate it, and transfer it to controlled storage when needed.
Store the relevant metadata alongside the asset, including the model identifier, creation timestamp, user ownership, output format, and any applicable retention deadline.
For sensitive media, avoid relying on obscurity of a generated URL as an access-control mechanism.
Before processing confidential or customer-owned material, review data handling, retention, licensing, and applicable contractual terms.
fal.ai Pros and Cons
fal.ai's strongest advantages are its developer-oriented media ecosystem and deployment flexibility. Its main limitations are the complexity of comparing costs and the need to manage production constraints carefully.
| Pros | Cons |
|---|---|
| Broad image and video model coverage | Prices vary significantly by endpoint |
| Useful model schemas and examples | Different billing units complicate comparisons |
| Playground-based experimentation | Some commercial models have cheaper alternatives |
| Asynchronous jobs and queue workflows | Throughput requires concurrency planning |
| Custom GPU deployment through Serverless | Idle runner time can affect compute costs |
| Model-specific creative features | Endpoint parameters and licenses vary |
| Convenient hosted inference | Output storage and access controls need attention |
These trade-offs are not equally important to every team.
A developer testing several creative models may value catalog breadth more than a small price difference. A business generating 100,000 images each month may prioritize cost per accepted image and operational predictability.
fal.ai vs LinkModel vs Replicate: Which Is Better?
The best alternative to fal.ai depends on whether you need creative-model breadth, managed access to commercial models, community-hosted models, or custom GPU infrastructure.
| Platform | Main strength | Main consideration | Best-fit use case |
|---|---|---|---|
| fal.ai | Creative-model endpoints and custom Serverless GPU | Model-specific pricing and operational limits | Media applications and custom inference |
| LinkModel | Unified access to supported commercial models with competitive published rates | Verify model availability and feature compatibility | Cost-focused applications using text, image, and video |
| Replicate | Hosted model ecosystem and model deployment workflows | Pricing and capabilities vary by model | Experimentation and community or official models |
| Atlas Cloud | Broad hosted model selection | Endpoint tiers and prices need individual comparison | Multi-model evaluation |
| WaveSpeedAI | Creative image and video model access | Availability and commercial terms vary | Media-generation workflows |
This is a capability-oriented comparison, not a measured performance ranking. No provider should be assumed to have the lowest latency or highest reliability without controlled testing.
When fal.ai is the better choice
Choose fal.ai when the model you need is available there with the right features, or when its Serverless infrastructure allows you to deploy a custom workflow that another hosted API cannot support.
Its model-specific tooling can also reduce integration effort when your application uses several specialized media endpoints.
When LinkModel is the better choice
LinkModel is worth evaluating when your production application relies on supported commercial models and you want to reduce generation costs without managing separate GPU deployments.
The published Gemini 3.1 Flash Image comparison illustrates a concrete advantage: $0.05025 per standard 1K image through LinkModel versus $0.08 through fal.
LinkModel also provides a catalog covering text, image, and video models under a unified service. This can simplify provider management for applications that use multiple modalities.
However, developers should still confirm model identifiers, supported parameters, SDK compatibility, response formats, rate limits, retention policies, and real-world output quality before migrating.
For a more focused breakdown, see the LinkModel vs fal.ai comparison.
Which Platform Should You Choose for Your Workload?
The most useful purchasing decision starts with the actual workload rather than a platform-wide ranking.
| Your workload | Start by evaluating | Most important metric |
|---|---|---|
| Exploring many creative models | fal.ai | Model availability and integration effort |
| Generating large volumes of commercial-model images | LinkModel and fal.ai | Cost per accepted image |
| Building a custom GPU inference service | fal Serverless and compute alternatives | Cost per successful inference |
| Creating a commercial AI video application | Both hosted providers | Quality, latency, and accepted-video cost |
| Using several text, image, and video models | Unified API providers | Coverage and total integration cost |
| Testing community-hosted models | Replicate and fal.ai | Model availability and deployment flexibility |
Before committing to a provider, run a small representative pilot using the same production prompts and settings.
Compare output acceptance, end-to-end latency, failure behavior, total billing, and the engineering work needed to maintain the integration.
A provider that is cheaper per request but requires substantially more retries or manual intervention may not be the cheapest in practice.
Frequently Asked Questions
Is fal.ai worth it in 2026?
Yes, for developers who need its creative-model catalog, asynchronous generation workflows, or custom Serverless GPU capabilities. For applications using only a few commercial models, compare endpoint-level pricing and performance before choosing.
Is fal.ai free?
fal may offer promotional or trial credits, but the amount and eligibility can change. Production usage generally requires paid billing. Check current account offers and credit conditions rather than assuming a fixed free allowance.
Can I use fal.ai for commercial applications?
Many endpoints support commercial use, but licenses and usage conditions can differ by model. Check the exact model page and relevant provider terms before using generated outputs commercially.
How long does fal.ai store generated media?
fal has described generated media availability of at least seven days. Retention and access-control policies should be verified for the current service and endpoint. Store important assets in infrastructure you control.
Is LinkModel cheaper than fal.ai?
For some supported commercial models, yes. The published Gemini 3.1 Flash Image standard 1K rates show LinkModel at $0.05025 versus fal at $0.08. That does not establish a price advantage across every model or endpoint.
What is the best fal.ai alternative?
LinkModel is a strong option for cost-sensitive applications using supported commercial models. Replicate is worth considering for hosted community and official models, while other creative-model providers may be useful for specific image and video workloads. The best alternative is the one that supports your required model and features at the lowest acceptable total cost.
Final Verdict: Should You Use fal.ai?
fal.ai remains a compelling platform for generative media development, especially when access to specialized models, asynchronous inference, and custom GPU deployment matters. Its developer tooling and flexible infrastructure are meaningful strengths.
The main reason to compare alternatives is cost—not because fal.ai is universally expensive, but because pricing differs substantially across models and providers.
For high-volume applications using selected commercial models, LinkModel's published rates can offer a measurable generation-cost advantage. Its Gemini 3.1 Flash Image pricing is one example, while Seedance 2.0 illustrates why billing-unit normalization and feature matching are essential.
Choose fal.ai when its particular models or deployment capabilities justify the platform. Evaluate LinkModel when you want supported commercial models, unified API access, and competitive published pricing.
Ultimately, the right provider is the one that delivers the lowest cost per accepted output while meeting your requirements for quality, latency, reliability, and data handling.
Compare Commercial AI Model Pricing on LinkModel
Access supported GPT, Claude, Gemini, Seedance, and other AI models through a unified platform. Compare published model prices, review supported capabilities, and test the endpoints that match your application before committing to production.
Explore Models and Pricing on LinkModel
Pricing and feature references reviewed October 15, 2026. Provider rates, availability, account limits, and service terms may change. Calculated workload examples are estimates, not independent performance tests.