GPT Image 2.5 leads the verified image preference rankings, while Nano Banana 2.1 offers lower official input rates and clearer resolution-based output costs. A five-task comparison favors Flare for photography, editing, and character preservation, but Nano Banana 2.1 for product composition. Better value depends on your brief and cost per accepted image.
Changed packaging, missing copy space, or drifting character identity can turn an attractive image into another failed attempt. Retries and manual corrections can erase a low generation price, so reducing AI API costs requires more than comparing a model's best-looking output.
Nano Banana 2.1 and GPT Image 2.5 are both available on LinkModel, with a 25% API discount on Nano Banana 2.1 compared to Google's official token rates. Nano Banana 2.1 starts at $1.125 per million input tokens and $22.50 per million output tokens on LinkModel, while GPT Image 2.5 pricing starts at $0.00441 per image, depending on configuration. With pay-as-you-go billing, no minimum spend, and no monthly platform fee, you can compare both models and scale the workflow that delivers the best results for your budget. Explore the Nano Banana 2.1 API discount to get started at a lower cost.
Nano Banana 2.1 vs GPT Image 2.5: The Main Differences
This comparison covers Nano Banana 2.1, GPT Image 2.5 Flare, and GPT Image 2.5 Sunburst. Flare and Sunburst must remain separate when discussing quality, editing, performance, and cost.
Our research combines official documentation, original leaderboard snapshots, and published same-task examples. Our review of user questions informs the acceptance criteria and FAQ. The image cases are third-party experiments; LinkModel’s contribution here is source verification and workflow analysis.
Nano Banana 2.1: References, Resolution, and Search Grounding
According to Google’s model documentation, Nano Banana 2.1 supports 1K, 2K, and 4K output, up to 14 reference images, Google Web and Image Search grounding, and configurable thinking levels.
These features make it relevant to reference-heavy compositions and grounded visual content. They establish supported functionality rather than a guaranteed advantage in output quality.
For a product scene, one reference might define geometry while another defines lighting. Specify those roles clearly. Otherwise, the model must infer which details to preserve, and the reviewer has no consistent standard for accepting the result.
GPT Image 2.5 Flare vs Sunburst
In OpenAI’s Sunburst documentation, editing precision is the recommended selection criterion. The Flare documentation positions Flare for everyday generation where speed matters.
Both share published token rates. Equal rates do not establish equal token consumption, latency, or cost per image.
The Flare vs Sunburst distinction also matters for evidence. The five-task study below tested Flare. Sunburst’s leaderboard scores are a separate result and cannot be presented as measured performance on those five tasks.
Nano Banana 2.1 vs GPT Image 2.5 Benchmarks: Which Leads on Quality?
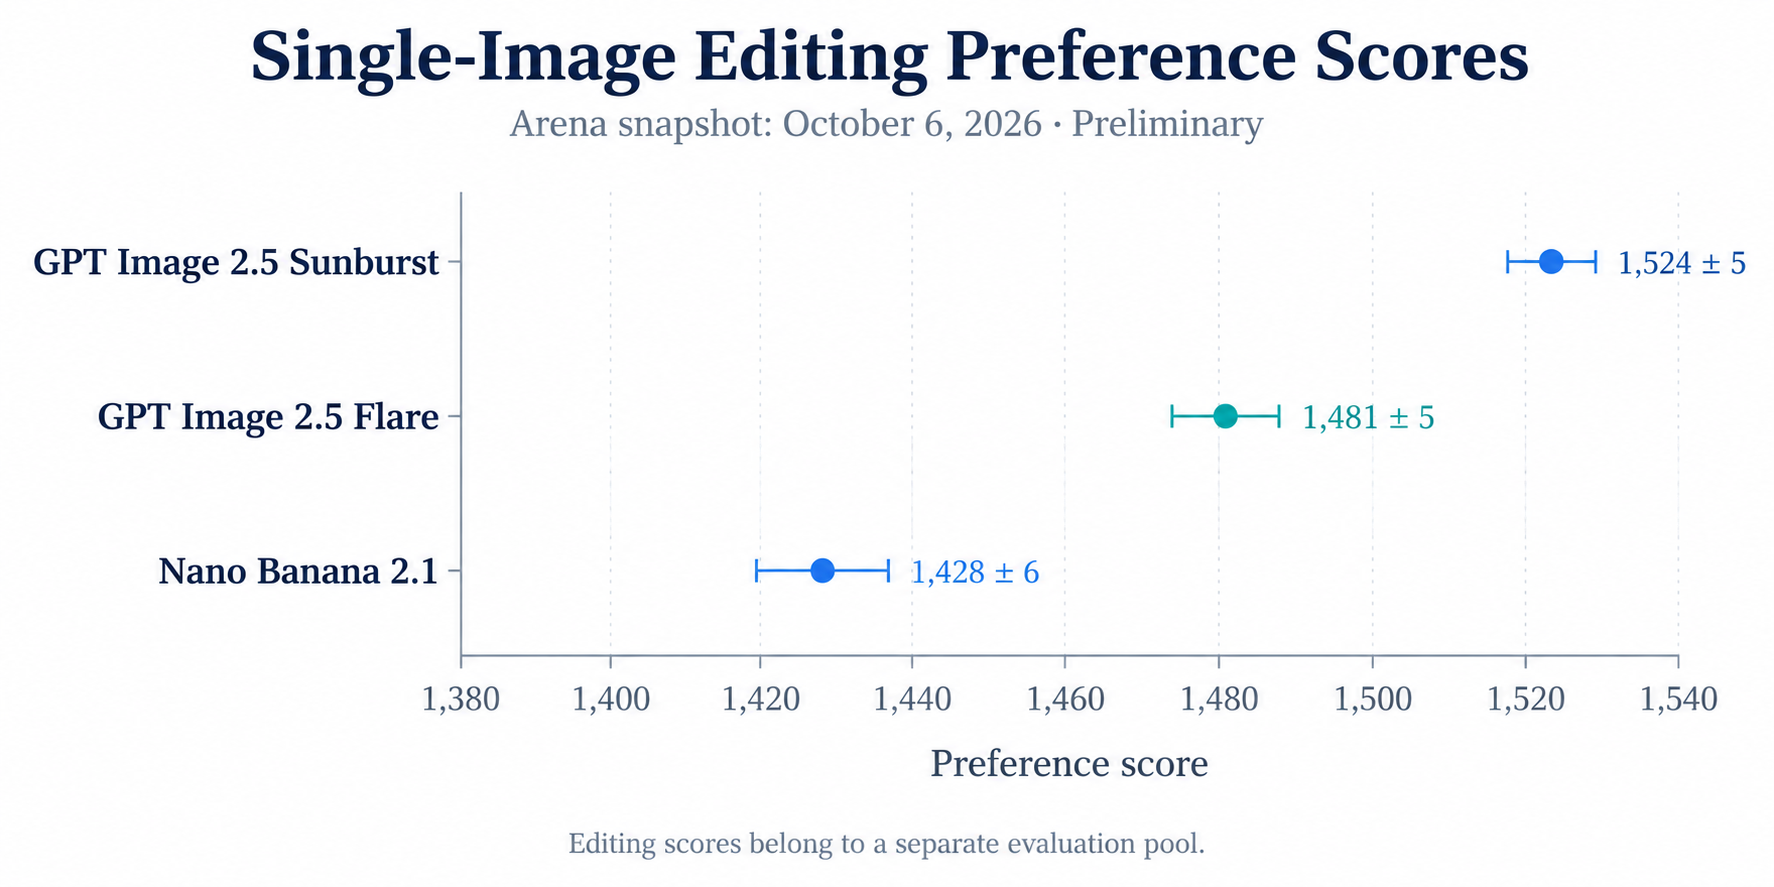
GPT Image 2.5 leads the reviewed Arena preference snapshots for generation and single-image editing. These rankings provide broader evidence than a few examples, but they do not predict your product’s acceptance rate.
Text-to-Image Generation Scores
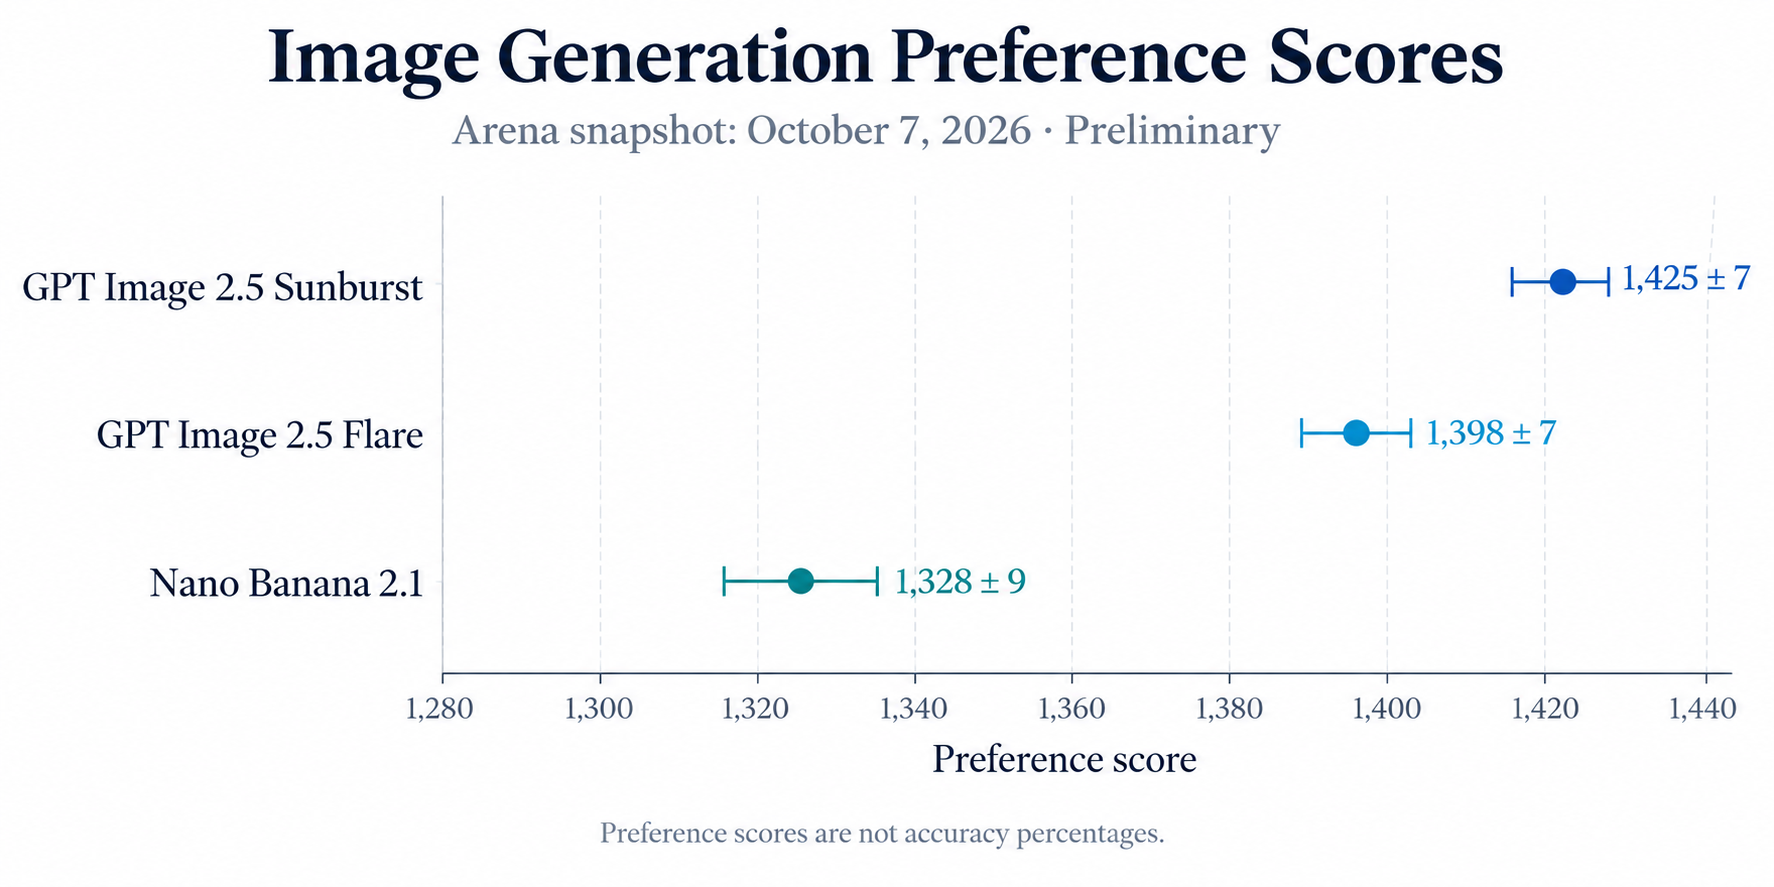
The October 7, 2026 snapshot on Arena’s generation leaderboard reported:
- Sunburst: 1,425 ± 7, with 17,752 listed votes.
- Flare: 1,398 ± 7, with 16,889 listed votes.
- Nano Banana 2.1: 1,328 ± 9, with 5,310 listed votes.
All three entries were preliminary.
These results justify including both GPT Image 2.5 variants in a quality shortlist. They do not establish which model will follow a particular layout, preserve a product label, or produce an acceptable image within a fixed budget.
Single-Image Editing Scores
The separately dated October 6 snapshot on Arena’s editing leaderboard reported:
- Sunburst: 1,524 ± 5, with 59,825 listed votes.
- Flare: 1,481 ± 5, with 57,408 listed votes.
- Nano Banana 2.1: 1,428 ± 6, with 12,985 listed votes.
These entries were also preliminary.
Preference scores are not accuracy percentages. A score gap cannot be converted into a percentage improvement in image quality. Generation and editing scores also belong to different evaluation pools.
The useful next step is to test the shortlisted models against your hardest requirements, rather than treating the leaderboard as a purchasing decision by itself.
Nano Banana 2.1 vs GPT Image 2.5 Image Quality: Five Real-World Tests
To compare Nano Banana 2.1 and GPT Image 2.5 beyond benchmark scores, we generated five sets of images covering photorealism, typography, product photography, skincare advertising, and character depiction.
All five comparisons use our own generated images, not results reproduced from third-party evaluations. GPT Image 2.5 appears on the left, while Nano Banana 2.1 appears on the right in every comparison.
The goal is to examine how each model handles practical visual requirements: lighting, composition, typography, material realism, product presentation, and recognizable character features.
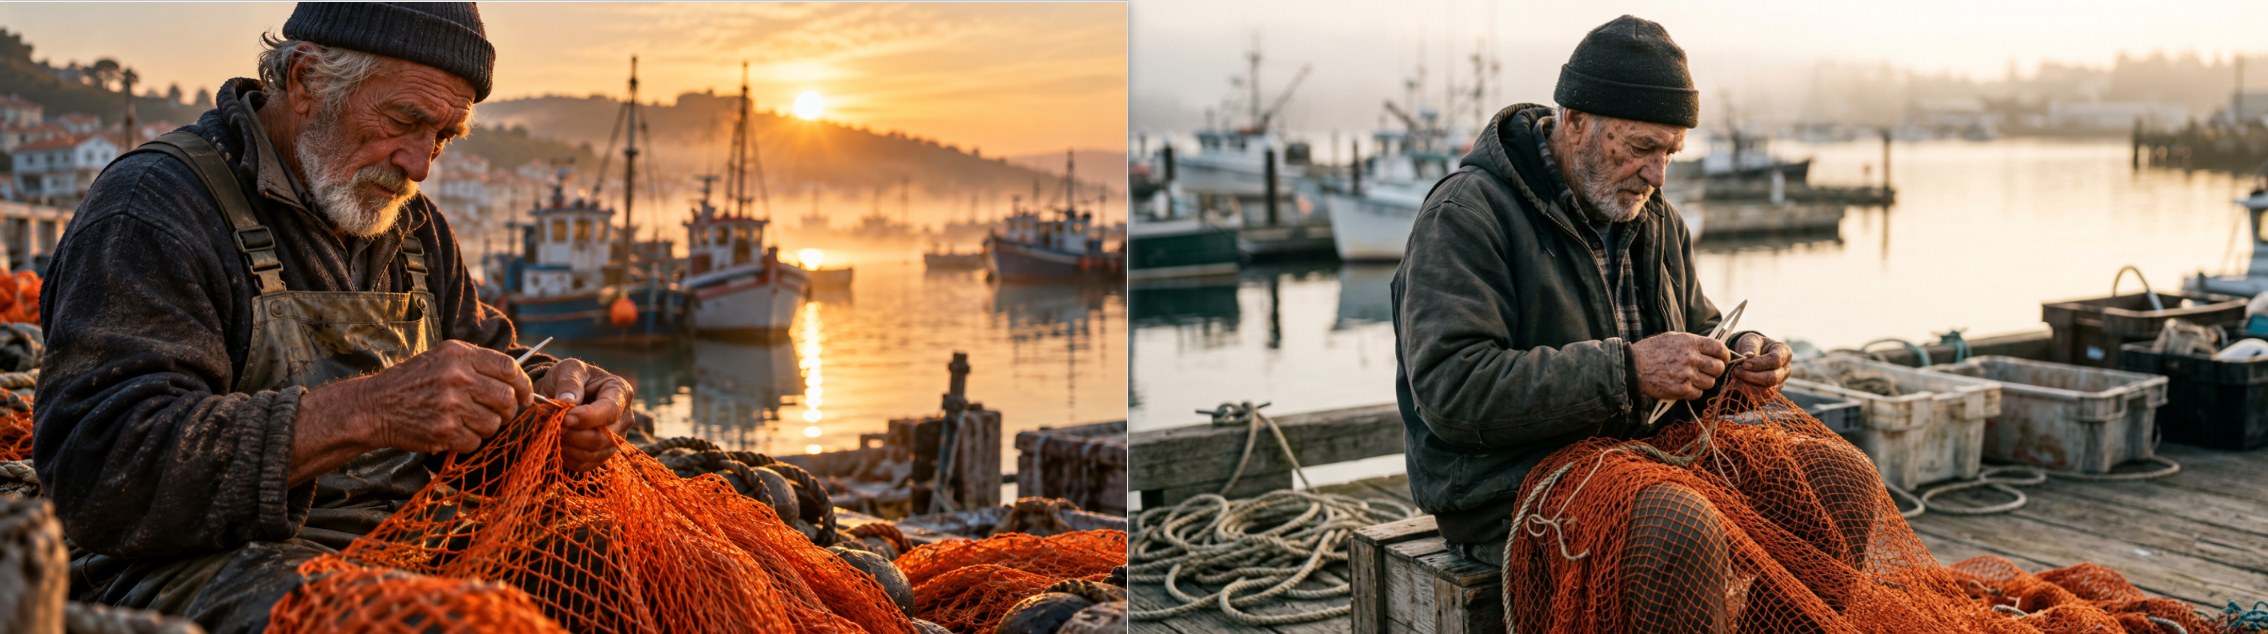
Photorealism: A Fisherman at Dawn
The first test features an elderly fisherman repairing a bright orange fishing net at dawn. Both models successfully capture the subject, weathered clothing, fishing equipment, and peaceful harbor atmosphere, but their photographic styles differ noticeably.
GPT Image 2.5 delivers a warmer, more cinematic result. The low golden sun creates strong highlights across the fisherman's face and hands, while the vibrant orange net provides a striking focal point. The closer framing also makes the human subject more emotionally engaging.
Nano Banana 2.1 takes a more restrained documentary approach. Its softer lighting, muted colors, and wider framing reveal more of the working harbor. The fisherman appears naturally integrated into the environment, with fishing boats, ropes, and equipment contributing to the scene's authenticity.
The difference is especially visible in the lighting. GPT Image 2.5 emphasizes dramatic golden-hour photography, whereas Nano Banana 2.1 favors a quieter, more atmospheric morning scene.
For editorial portraits and visually striking storytelling, GPT Image 2.5 has the stronger immediate impact in this example. Nano Banana 2.1 may be preferable when environmental context and understated realism are the priorities.
Key takeaway: GPT Image 2.5 stands out for cinematic lighting and subject emphasis, while Nano Banana 2.1 offers a more subdued documentary composition.
Typography: The NIGHT TIDE Poster
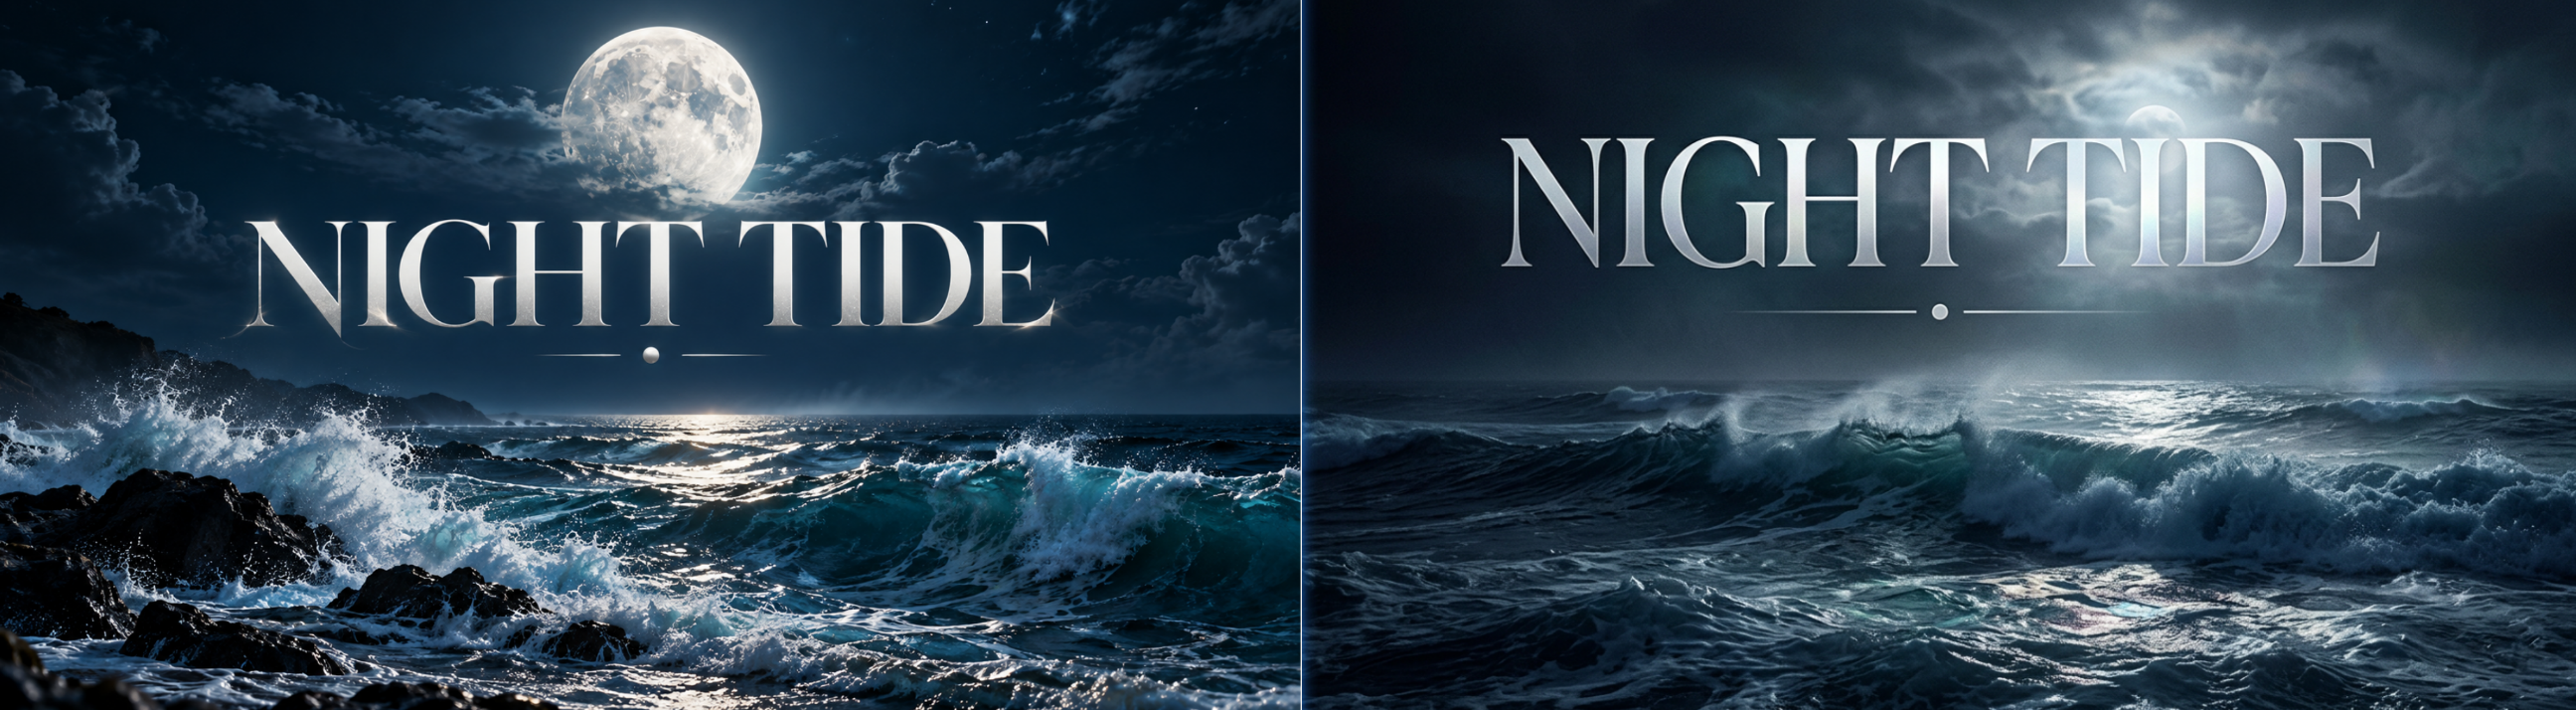
The second test examines how both models combine typography with atmospheric poster design. The creative concept centers on the words "NIGHT TIDE," a moonlit ocean, and a sophisticated nighttime aesthetic.
Both models reproduce the main title clearly and create visually coherent designs. However, GPT Image 2.5 produces a more dramatic, high-contrast composition, with a prominent moon, illuminated waves, and bright silver lettering. The typography feels integrated into a cinematic coastal scene.
Nano Banana 2.1 uses a darker, more restrained visual treatment. Its large metallic lettering dominates the upper portion of the image, while the ocean and mist establish a moody background. The overall composition feels closer to a minimalist promotional poster.
Both images also include a small circular punctuation element beneath the title. The main wording is legible in each result, although the exact decorative punctuation and typography should still be checked against the intended design specification.
For marketing teams, the choice depends on the desired visual identity. GPT Image 2.5 creates a more energetic and visually layered poster, while Nano Banana 2.1 offers a cleaner, more subdued aesthetic.
Key takeaway: Both models handle the main typography effectively. GPT Image 2.5 emphasizes visual drama, while Nano Banana 2.1 favors simplicity and restrained presentation.
Product Photography: A Ceramic Coffee Dripper
Commercial product photography requires more than realistic materials. The image must also communicate the product's design, create an appealing atmosphere, and leave enough space for potential advertising content.
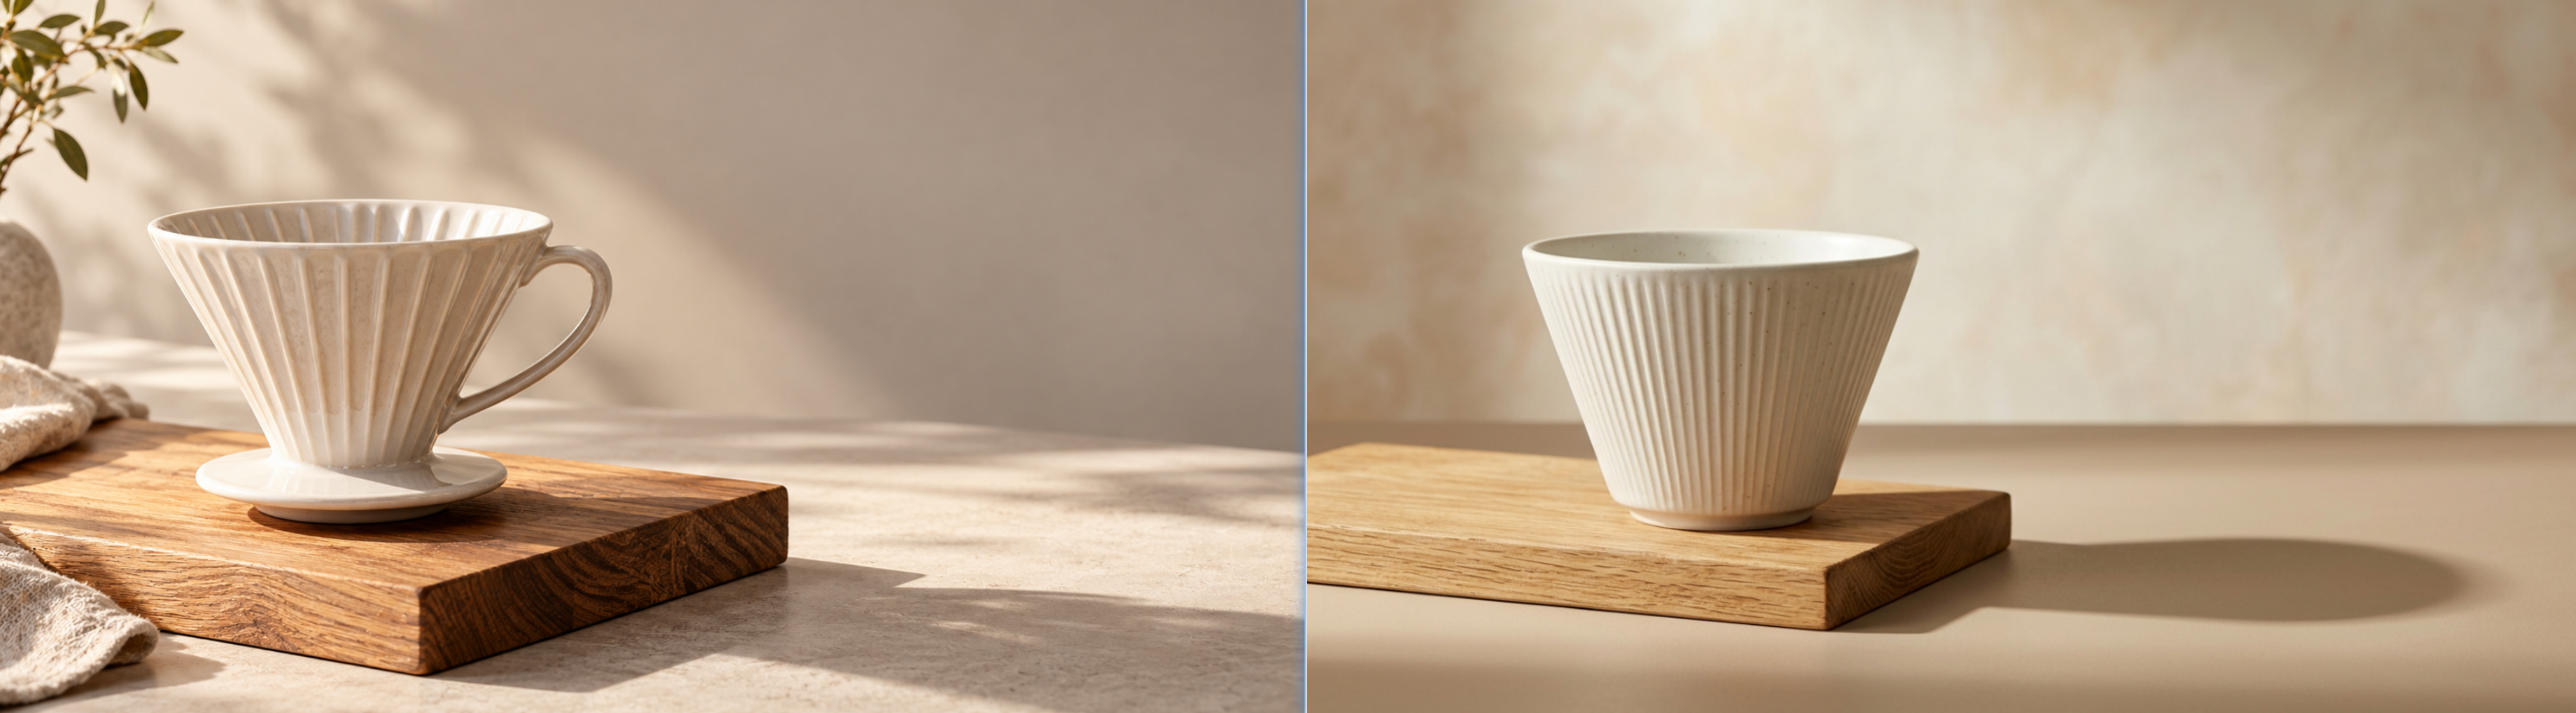
In this test, both models generate an ivory ceramic coffee dripper on a separate wooden board, illuminated by warm natural light. Both compositions are suitable for a minimalist lifestyle or homeware campaign, but the product details differ.
GPT Image 2.5 creates a more lifestyle-oriented photograph. Its ceramic dripper includes a prominent handle, matching base, and glossy finish. The thick oak board, textured fabric, and subtle greenery make the scene feel like a carefully styled coffee advertisement.
Nano Banana 2.1 produces a simpler, more product-focused composition. Its handleless ceramic dripper has fine vertical ridges and a matte appearance. The clean wooden board, neutral background, and uncluttered surroundings place greater emphasis on the product's shape.
Both images provide usable negative space, although GPT Image 2.5 offers a particularly open area to the right of the product. Nano Banana 2.1 creates a more balanced and restrained arrangement with fewer decorative elements.
One important difference is product interpretation. The two drippers are not identical: their handles, bases, and silhouettes differ. That matters when the goal is to represent a specific commercial product rather than generate a general lifestyle image.
Key takeaway: GPT Image 2.5 offers richer lifestyle styling, while Nano Banana 2.1 delivers a cleaner product presentation. For e-commerce use, product-design accuracy remains essential.
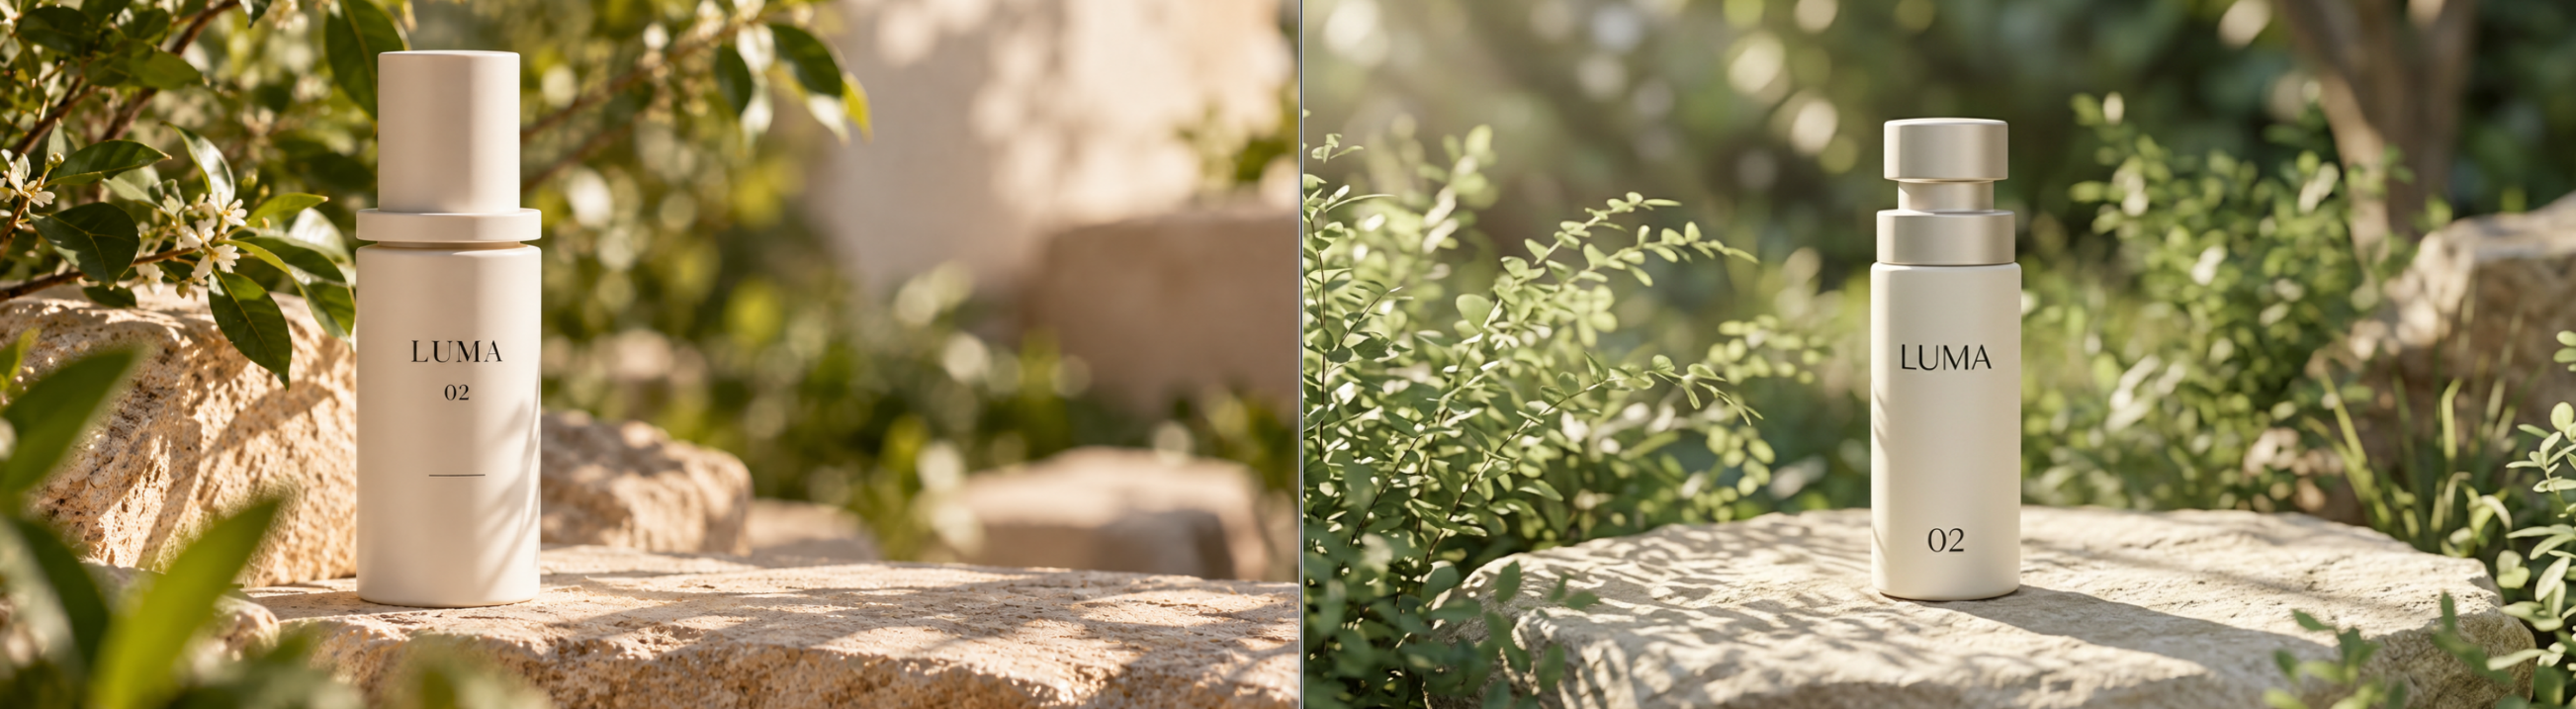
Background Replacement: The LUMA 02 Bottle
The fourth test focuses on premium skincare advertising, where packaging details, natural lighting, and background composition must work together to communicate a consistent brand identity.
Both models place a minimalist LUMA bottle in a botanical outdoor environment, using natural stone, greenery, and warm sunlight to create a luxury skincare aesthetic.
GPT Image 2.5 produces a more polished, close-up advertising composition. The bottle occupies a larger portion of the frame, with soft sunlight and botanical shadows adding visual interest. The label is presented as "LUMA" with "02" directly beneath it, and the bottle has a relatively simple cylindrical cap structure.
Nano Banana 2.1 uses a wider composition with more visible greenery. Its bottle appears smaller within the scene, creating additional environmental context. The packaging also differs: the cap includes a more pronounced stepped structure, and the label places "02" considerably lower on the bottle.
These differences reveal an important challenge in AI-generated product photography: models can produce attractive images while interpreting the same product concept differently.
Both results look commercially appealing, but neither image alone establishes which model would better preserve an existing product. That would require comparison against the same approved reference image.
For brand campaigns, visual quality must be evaluated alongside packaging consistency, label placement, cap geometry, and the accuracy of the final product representation.
Key takeaway: GPT Image 2.5 creates a stronger close-up product focus, while Nano Banana 2.1 provides more environmental context. Both require packaging verification before commercial use.
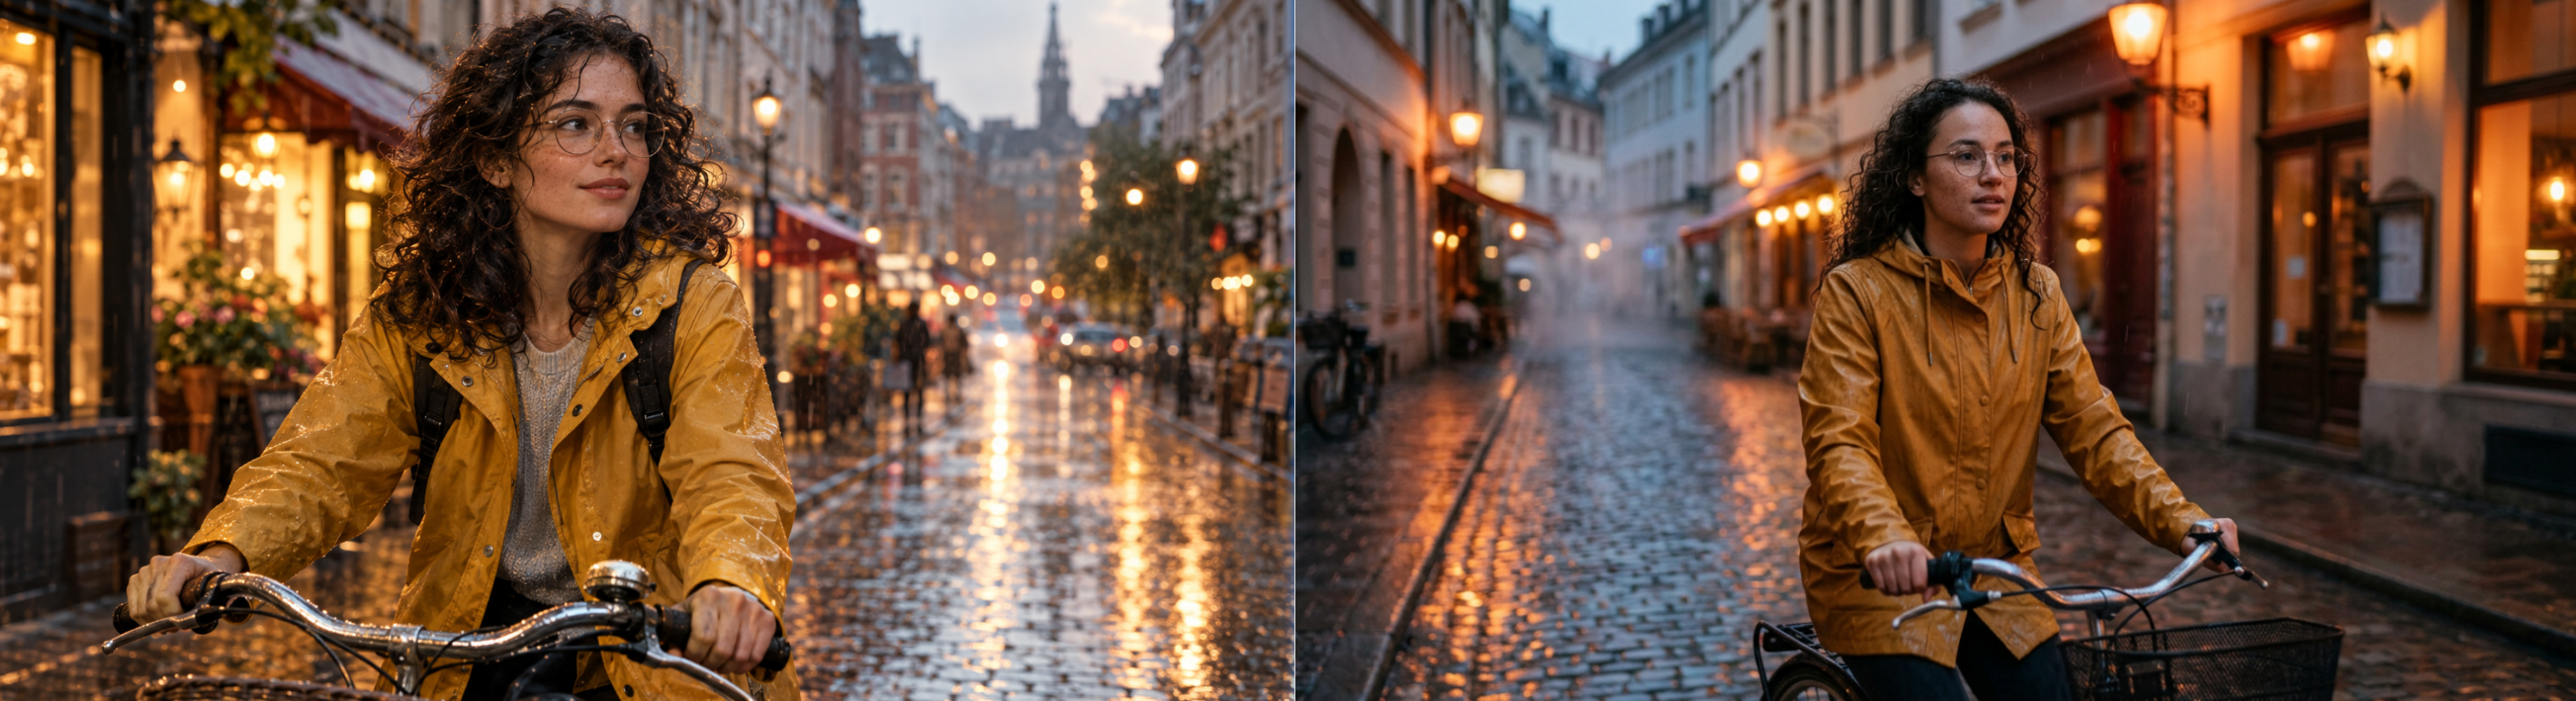
Character Consistency: A Rainy Cycling Scene
The final test examines how the two models depict a recognizable character in a cinematic urban environment. The scene features a young woman with curly dark hair, freckles, round glasses, and a mustard-yellow rain jacket riding a bicycle through a rain-soaked European street.
Both models capture the essential character description, wet cobblestones, warm street lighting, and atmospheric evening setting.
GPT Image 2.5 produces a closer, more expressive character portrait. The woman's curly hair, round glasses, facial features, and rain jacket are clearly visible. The background uses warm reflections and shallow depth of field to create a visually engaging editorial photograph.
Nano Banana 2.1 presents a wider environmental composition. The cyclist appears farther from the camera, allowing more of the street, architecture, and bicycle to remain visible. The lighting is softer, and the scene places greater emphasis on the character's surroundings.
The difference is also noticeable in character presentation. GPT Image 2.5 emphasizes facial detail and visual personality, while Nano Banana 2.1 prioritizes a broader view of the action and environment.
However, this example measures character depiction rather than true character consistency. Both models generate a character matching the description, but a reliable consistency test would require multiple images of the same reference character across different poses, scenes, and camera angles.
Key takeaway: GPT Image 2.5 performs well in close-up character presentation, while Nano Banana 2.1 provides stronger environmental coverage in this example. Consistency across multiple scenes remains a separate question.
Nano Banana 2.1 vs GPT Image 2.5 Editing: What Must Stay Unchanged?
Successful editing requires both accurate changes and reliable preservation. Overall visual appeal can conceal failures that make an output commercially unusable.
Divide the brief into required changes, protected attributes, and optional details. In a background replacement, lighting may change, the label must remain faithful, and background foliage may vary within approved limits.
This produces actionable rejection reasons. “Closure geometry changed” is more useful than “the image feels wrong.”
Reference Capacity vs Preservation Quality
Google documents up to 14 references. OpenAI’s editing API reference permits up to 16 input images for GPT Image models.
Those are input capacities, not consistency scores.
Additional views can clarify geometry or identity, but conflicting references can introduce ambiguity. In Nano Banana prompting, identify which image controls the product, pose, clothing, lighting, or style.
For multi-character scenes, review every person separately. A recognizable main subject does not establish that the supporting characters remain consistent.
Masks vs Exact Source Preservation
The OpenAI editing reference documents a mask input, providing a regional editing control.
A mask still requires output verification. Inspect protected labels, closures, logos, and fine edges rather than assuming they survived unchanged.
When exact source pixels are essential, compositing the original product over a generated background may be more controllable. That adds a production step, but it can fit strict catalog or packaging requirements.
Choose the workflow according to the required preservation standard.
Multi-Turn Editing: Review the Whole Revision Chain
The five-task study does not measure repeated revisions. It cannot establish how either model performs after several edits.
For a revision-heavy workflow, compare each result against both the previous image and the approved source. Check whether labels, identity features, materials, or sharpness drift as changes accumulate.
Use separate acceptance checks for the newest change and previously approved details. A successful revision should not reopen a problem already resolved.
Multi-turn reliability needs its own test, rather than being inferred from a single edit.
Nano Banana 2.1 vs GPT Image 2.5 Pricing: What Does an Image Really Cost?
Nano Banana has lower official Standard input rates, while both families charge $30 per million image output tokens. Complete request costs still depend on consumption and configuration.
Our review of Google’s pricing documentation found Standard input at $1.50 per million tokens and text or thinking output at $7.50 per million tokens.
The OpenAI model pages list Standard text input at $5 and image input at $8 per million tokens.
These are direct-provider rates. They should not be confused with LinkModel listings or reseller prices.
Nano Banana 2.1 Output Costs at 1K, 2K, and 4K
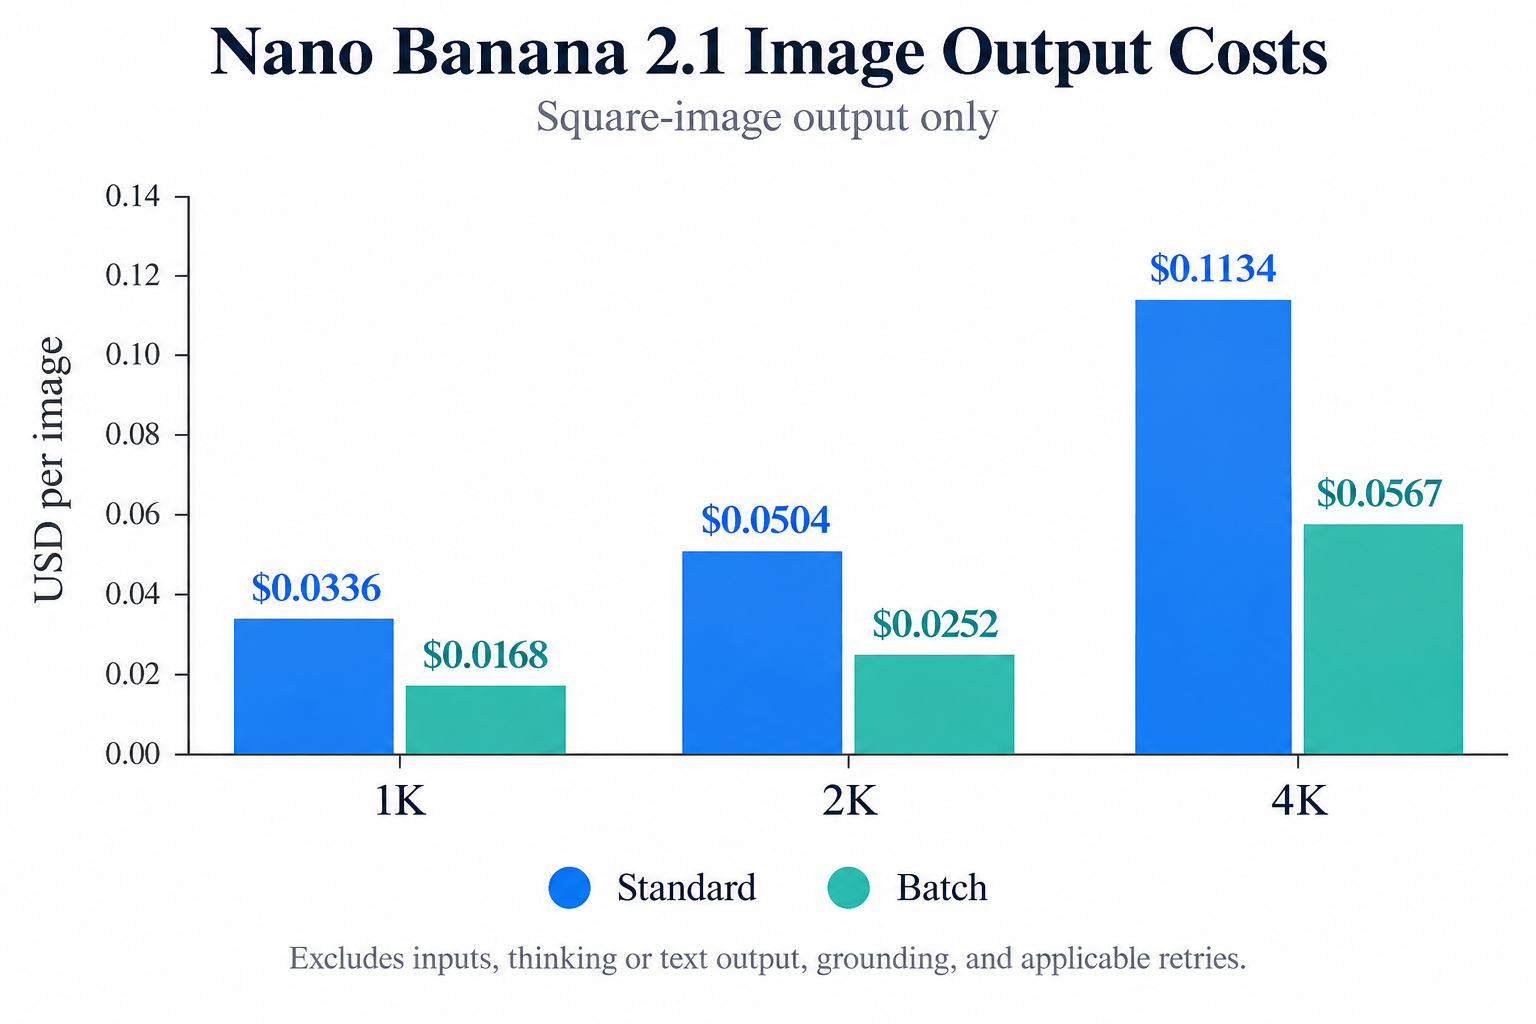
Google publishes square-image output token counts supporting these calculations:
- 1K: 1,120 tokens; $0.0336 Standard or $0.0168 Batch.
- 2K: 1,680 tokens; $0.0504 Standard or $0.0252 Batch.
- 4K: 3,780 tokens; $0.1134 Standard or $0.0567 Batch.
The 4K Standard calculation preserves precision; Google displays a rounded $0.113 equivalent.
For 10,000 generated images, Standard image output alone would cost $336 at 1K, $504 at 2K, or $1,134 at 4K. Batch output would cost $168, $252, or $567 respectively.
Inputs, thinking or text output, grounding, and applicable retries remain additional costs.
GPT Image 2.5: Calculate from the Actual Request
According to OpenAI’s billing guide, consumption can differ by model and quality setting. Responses workflows also incur mainline model usage.
At Standard rates:
Image output cost = output tokens × $30 ÷ 1,000,000
For illustration, 2,000 output tokens cost $0.06 and 4,000 cost $0.12. These are calculations, not measured costs for a particular configuration.
Add input charges and applicable workflow usage. Cached image-generation input discounts have endpoint-specific conditions.
For a reproducible budget, retain:
- Exact model and quality setting.
- Output dimensions and image count.
- Reference inputs.
- Reported token usage.
- Complete billed amount.
- Acceptance or rejection reason.
No measured complete-request bills are available in this review. The figures above should not be presented as full production costs.
Cost per Accepted Image: Account for Retries
Use:
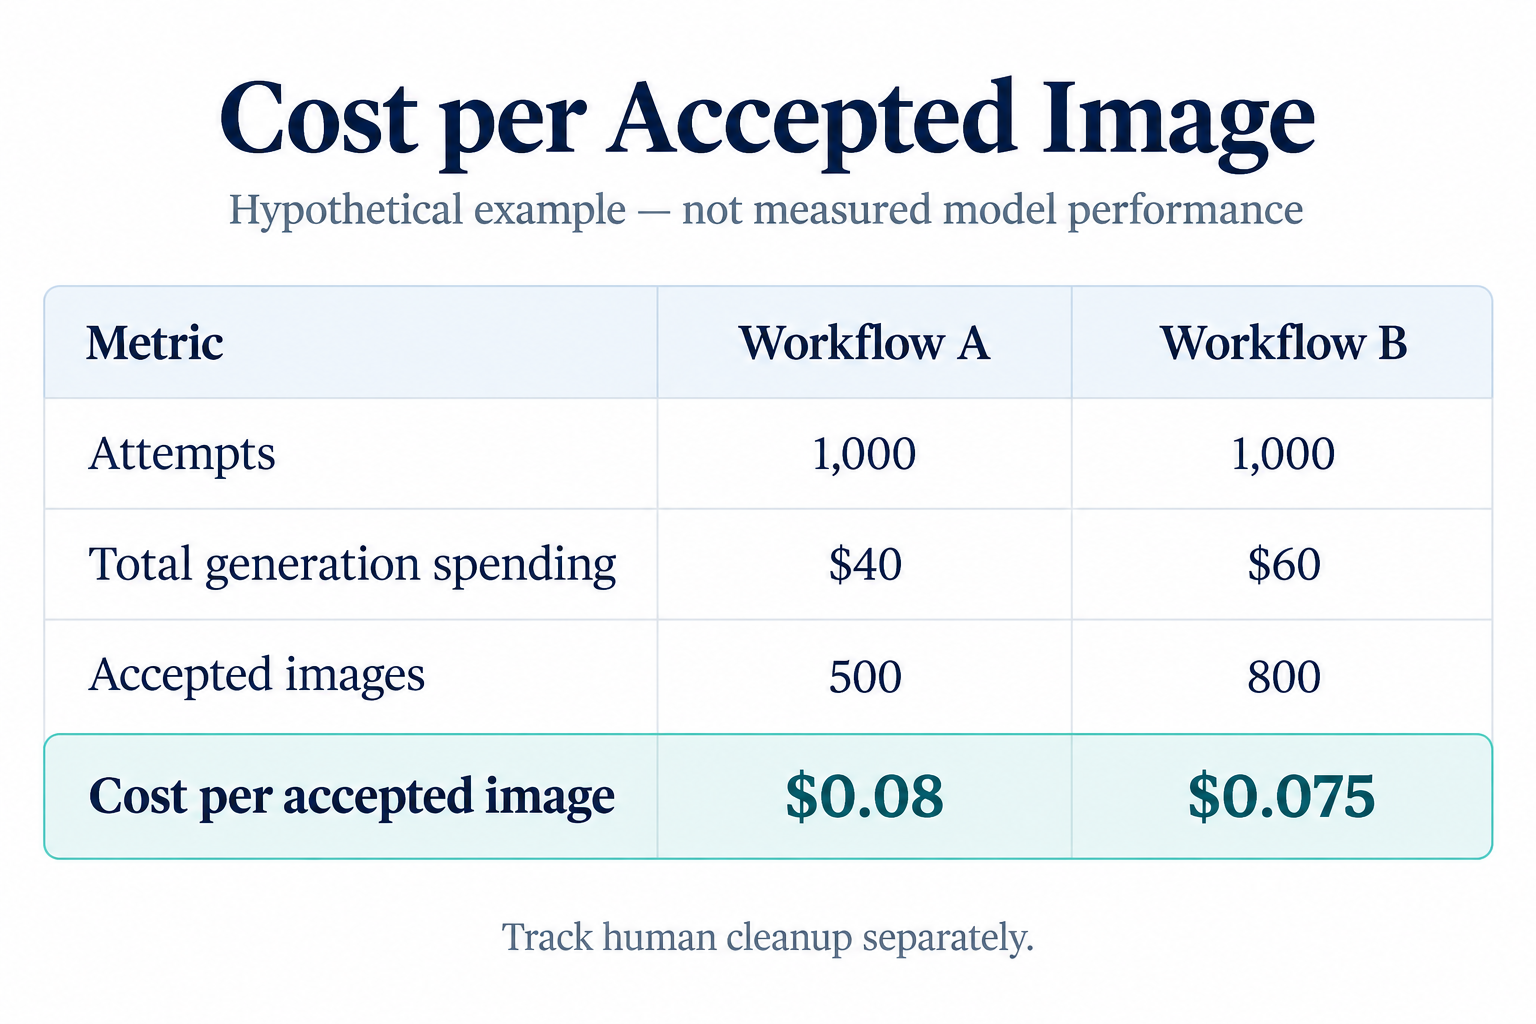
Cost per accepted image = total generation spending ÷ accepted outputs
Consider two hypothetical batches of 1,000 attempts. Workflow A spends $40 and produces 500 accepted images, costing $0.08 per accepted image. Workflow B spends $60 and produces 800 accepted images, costing $0.075.
Workflow B costs more per attempt but less per usable result. These examples explain the calculation; they do not describe measured model performance.
Track selection and retouching time separately. Frequent label repair or compositing can outweigh a small API saving.
LinkModel Pricing: Starting Rates Need Context
LinkModel’s listed $0.00441 GPT Image 2.5 starting price is not a fixed charge for every size, quality, or input configuration.
Check the applicable request price before comparing it with official token billing. The review did not verify the exact configuration or input-charge conditions behind that minimum.
When comparing low-cost image APIs, the useful commercial advantage is the ability to begin with a small pay-as-you-go workload. Evaluate actual spending and accepted outputs before scaling.
Compare equivalent jobs, not unlike pricing units.
Nano Banana 2.1 vs GPT Image 2.5 Performance: Speed, Failures, and Delivery
The reviewed evidence does not establish a matched latency winner across Nano Banana, Flare, and Sunburst. Historical aggregator figures were not reproducible as a comparable final-image dataset.
Measure completed delivery. An initial response or partial preview is a different event from receiving the finished asset.
Reliability also needs clear definitions. Uptime, valid-image return rate, and commercial acceptance rate measure different things.
Measure Final-Image Latency and Acceptance Together
When measuring AI API latency, record median and P95 completion times, valid-image return rate, and acceptance rate under consistent settings.
For example, a model may return images quickly but frequently miss a mandatory label or layout requirement. Those outputs increase time spent regenerating and selecting.
Time to an accepted image is more useful than the fastest individual response.
Keep technical failures separate from quality rejections. A request returning no valid image and a completed image failing the brief require different corrective actions.
Interactive Editing vs Batch Production
An interactive editor prioritizes short waits and clear progress. An overnight catalog job may prioritize total spending and deadline completion.
Evaluate those workloads separately. A simple generation request does not predict a reference-heavy editing job.
Log settings, duration, charges, errors, and acceptance reasons. This helps distinguish temporary service problems from a model consistently struggling with a task.
Nano Banana 2.1 vs GPT Image 2.5 API: Which Is Easier to Integrate?
The easier integration is the one that exposes your required controls and makes failures and charges understandable. Model availability alone does not establish a production-ready workflow.
Reference handling, formats, transparency, dimensions, and grounding all affect implementation effort.
Formats, Transparency, and Dimensions
OpenAI’s generation API reference documents PNG, JPEG, and WebP output, transparent backgrounds, and one to ten images per request.
Transparency can remove an additional cutout-processing stage. Explicit formats simplify downstream handling.
The reference permits custom dimensions within constraints, marks resolutions above 2560 × 1440 experimental, and lists a maximum supported resolution of 3840 × 2160.
Google’s square 4K output is 4096 × 4096. The “4K” label does not identify the same deliverable across providers.
Grounding and Reference Workflows
Nano Banana’s documented search grounding is relevant when visuals depend on retrieved information.
Retrieval and accurate rendering remain separate requirements. For an infographic, verify facts, dates, quantities, and generated wording before publication.
Grounding also belongs in the request budget through its separate charging conditions.
For reference workflows, define a source of truth for each attribute. That makes both prompting and acceptance review more precise.
Nano Banana 2.1 vs GPT Image 2.5: Which Should You Choose?
Start with your hardest acceptance requirement, then compare cost at that standard.
For photographic scenes and recurring characters, include Flare and Sunburst because of the preference evidence, then test them against Nano Banana on your actual briefs.
For product layouts, include Nano Banana because the published composition example shows the importance of spatial compliance.
For grounded visuals, evaluate Nano Banana’s search capabilities. For transparent assets, evaluate GPT Image 2.5’s documented export controls.
For product edits, inspect protected details in every shortlisted model’s output.
Run a Repeatable Selection Trial
Use representative tasks: a hero image, a product composition, a background replacement, a text-heavy design, and a reference-character scene.
Keep source assets and semantic instructions consistent. Use comparable delivery dimensions, disclose quality settings, and generate multiple results per task.
An initial ten generations per task can reveal recurring failures, although it remains exploratory. Review without model labels where practical and define rejection criteria before inspecting results.
Maintain two outcomes: best quality within a fixed budget and lowest cost at a fixed acceptance standard. Those questions can produce different choices.
Frequently Asked Questions
Is Nano Banana 2.1 Better Than GPT Image 2.5?
Neither is better for every task. GPT Image 2.5 leads the reviewed preference snapshots, while Nano Banana better followed one product composition brief. Test the exact variant against your requirements.
Which Model Is Cheaper After Retries?
Nano Banana has lower official Standard input rates, but consumption and acceptance rate determine the result. Divide total spending by accepted images, then track human cleanup separately.
Which Model Better Preserves Products and Characters?
Flare better preserved the tested cap structure and character features in the small published study. That does not establish universal preservation. Compare multiple outputs with the approved source.
Should I Choose Flare or Sunburst?
OpenAI positions Flare for everyday generation and Sunburst for editing precision. Sunburst leads the reviewed preference snapshots, but actual cost, acceptance, and completion time still need testing.
Is Nano Banana 2.1 Faster Than GPT Image 2.5?
This review does not establish a matched speed winner. Measure final-image latency and retries under equivalent delivery requirements. Time to an accepted image is the more useful production metric.
Conclusion
GPT Image 2.5 has the stronger verified preference-ranking evidence, while Nano Banana 2.1 offers lower official input rates, documented resolution-based output costs, and useful grounding and reference controls. The task examples show that photography, composition, editing preservation, and identity need separate evaluation. Our recommendation at LinkModel is to test representative briefs and choose using cost per accepted image, delivery time, and preservation quality, rather than a model’s best-looking example or lowest advertised price.