Jev API is TypeSafe's API for fast, structured AI decisions, including classification, agent routing, verification, and scoring. Unlike a conventional LLM that generates open-ended text, Jev uses three decision primitives—Noul, Choice, and Score—to return bounded probabilistic answers.
Jev 1.13 costs $0.042 per million input tokens, with free output tokens. To get started, obtain a TypeSafe API key, send a POST request to https://api.typesafe.ai/v1/systemone, and specify the model, state, and questions. This guide covers API access, pricing, working request examples, benchmarks, and production limitations.
For workflows that also require text generation or complex reasoning, Jev can serve as a decision layer alongside general-purpose LLMs. LinkModel provides access to supported generative AI models through a unified API, allowing developers to evaluate downstream models for cost, quality, and performance without treating LinkModel as a direct Jev API provider.
Last updated: October 12, 2026 — Updated API setup instructions, pricing information and workflow benchmarks.
What Is the Jev API?
The Jev API is TypeSafe’s typed decision API for turning text or structured application state into bounded probabilistic decisions. Instead of generating open-ended answers, Jev returns structured signals for yes/no gates, routing, classification, scoring, and verification through its Noul, Choice, and Score primitives.
TypeSafe introduced Jev on September 15, 2026 as its first public System One Model, a model class designed around typed probabilistic decisions for software automation.
A Jev request has three core parts:
| Component | Purpose |
| State | Text, JSON, records, logs, or application state to evaluate |
| Model | The Jev model version handling the request |
| Questions | One or more typed decisions Jev should make |
The current API uses the /v1/systemone endpoint. Requests are authenticated with a TypeSafe API key, while the request body contains the state, model, and typed questions Jev should evaluate.
The stable model is currently jev-1.13.0, while jev-latest points to the latest available release.
Why Jev API Is Different From a Normal LLM API
A conventional LLM workflow often follows:
Prompt → generated answer → parse → validate → execute
Jev is closer to:
State → typed probabilities → business rules → execute
That difference matters in automated systems.
A support router does not need a paragraph explaining why a ticket belongs to billing. A model router does not need an essay about task difficulty. The application needs a bounded answer, uncertainty information, and a deterministic rule for what happens next.
Our review of user questions shows this is also the clearest way to understand Jev: it is not simply a smaller chatbot. Its interface is designed around deciding, classifying, routing, scoring, verifying, and gating.
How to Get a Jev API Key
To use the Jev API directly, you need an API key from TypeSafe, the developer of the Jev decision model. The key authenticates requests to TypeSafe's System One endpoint.
Step 1: Open the TypeSafe Console
Visit the TypeSafe Console and sign in. Check your account's current API access and billing requirements before sending requests.
Step 2: Create Your API Key
Open the API keys section in the console and generate a new key. Copy the key to a secure location. Never expose it in frontend JavaScript, public repositories, or screenshots.
Step 3: Configure Your Environment
Store your TypeSafe API key in an environment variable to avoid exposing it in your application code.
For macOS or Linux:
export TYPESAFE_API_KEY="your_api_key"For Windows PowerShell:
$env:TYPESAFE_API_KEY="your_api_key"Replace your_api_key with your actual TypeSafe API key. These commands set the environment variable for the current terminal session only. Never expose your API key in public repositories or client-side code.
Step 4: Check Your API Configuration
Use the following configuration for TypeSafe's direct Jev API:
| Setting | Value |
|---|---|
| API provider | TypeSafe |
| Endpoint | https://api.typesafe.ai/v1/systemone |
| HTTP method | POST |
| Authentication | Bearer API key |
| Content type | application/json |
| Model | jev-1.13.0 or jev-latest |
The versioned model identifier is useful for reproducible production evaluations. The jev-latest alias may change as new versions are released.
Important: API keys are provider-specific. A TypeSafe key should not be assumed to work with third-party Jev gateways, and a LinkModel API key is not a substitute for TypeSafe authentication.
Jev API Noul, Choice and Score Explained
Noul, Choice, and Score cover the three main forms of bounded software decisions: binary, categorical, and ordinal.
| Primitive | What it answers | Example | Best use case |
|---|---|---|---|
| Noul | Is this true or false? | Is this ticket urgent? | Verification and gating |
| Choice | Which option fits best? | Which agent should handle this? | Routing and classification |
| Score | How severe or important is it? | How serious is this incident? | Risk and priority scoring |
Choose Noul for binary decisions, Choice for selecting among predefined options, and Score for ordered evaluations. The best primitive depends on the decision your application needs to make.
Noul: Jev API Yes/No Decisions
Noul answers a binary semantic question and returns the probability of yes from 0 to 1.
A workflow might ask whether a support request is urgent, whether retrieved evidence supports a claim, or whether a task needs escalation.
Noul works especially well as a gate:
Input → Noul decision → continue, reject, or escalate
Unlike Choice and Score, Noul does not return a separate confidence field. Its probability is the main decision signal.
Choice: Jev API Routing and Classification
Choice selects the most likely option from a predefined candidate set and returns probabilities across the available choices.
Typical uses include:
- Agent routing
- Model routing
- Department classification
- Tool selection
- Intent detection
- Workflow branching
Choice currently supports up to 255 options.
That limit creates an important production rule. If an application contains 100,000 products, tools, or documents, do not use Choice as the retrieval layer.
A stronger architecture is:
Large candidate pool → retrieval → shortlist → Jev Choice → execution
Retrieval finds plausible candidates. Jev makes the semantic decision among them.
Score: Jev API Ordered Judgments
Score evaluates state against 2–10 ordered levels and returns a probability-weighted result.
Instead of asking for an arbitrary risk number from 0 to 100, define levels with explicit meaning:
Low → Moderate → High → Critical
The result can fall between levels because it is calculated from the probability distribution.
This structure works well for risk, support priority, lead quality, severity, customer frustration, and other ordinal decisions because every level has a defined business meaning.
Jev API Pricing, Latency and Limits
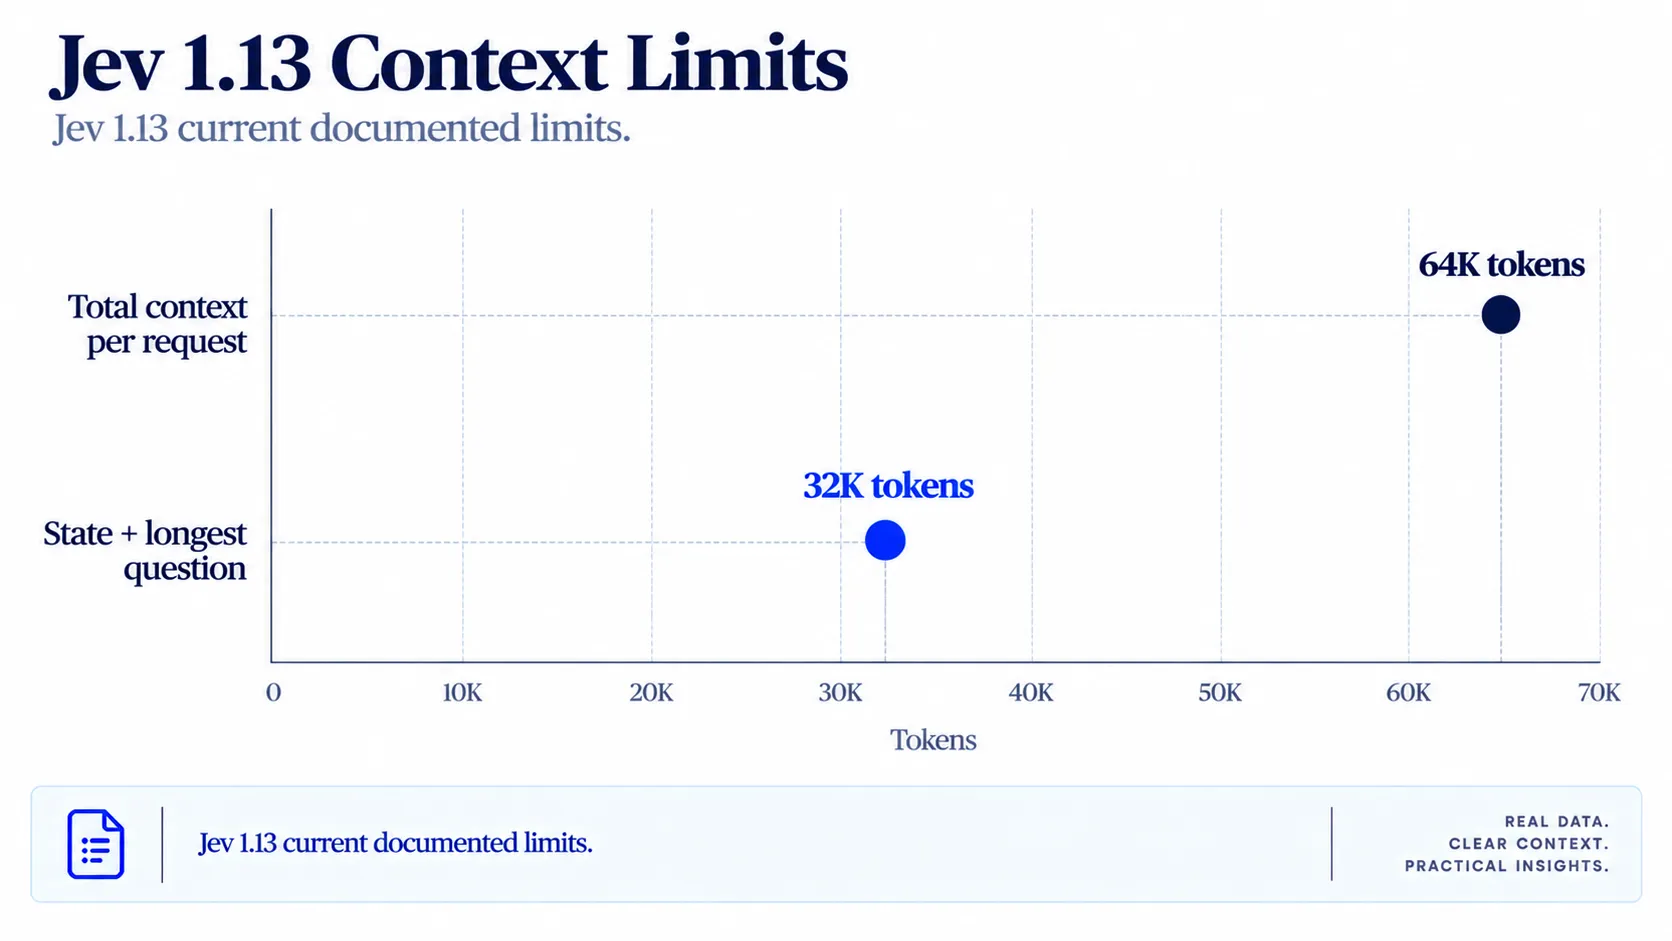
Jev 1.13 combines $0.042/M input-token pricing and free output with a published 70–500 ms response range, a 64K context window, and documented throughput and rate limits. The table below summarizes the current Jev 1.13 specifications.
| Metric | Jev 1.13 |
| Input price | $0.042 / 1M tokens |
| Output price | Free |
| Published response time | 70–500 ms |
| Context | 64K tokens |
| State + longest question | 32K tokens |
| Rate limit | 1,200 requests/min |
| Throughput | 250,000 tokens/sec |
| Choice options | Up to 255 |
| Score levels | 2–10 |
| Input modality | Text |
These economics become more important as decision volume grows.
If an application makes one classification per hour, the architecture may not matter much. If an agent platform makes hundreds of thousands of routes, verification checks, or gates, the decision layer becomes part of the product’s cost and latency profile.
How Much Does Jev API Cost?
TypeSafe lists Jev 1.13 at $0.042 per million input tokens, with no output-token charge. The cost of a request therefore depends mainly on the amount of state and question context submitted to the model.
The basic calculation is:
API cost = Input tokens ÷ 1,000,000 × $0.042
The following examples use the published input-token rate and assume no additional provider-specific charges.
| Input tokens per request | Cost per request | Cost for 100,000 requests |
|---|---|---|
| 500 | $0.000021 | $2.10 |
| 1,000 | $0.000042 | $4.20 |
| 5,000 | $0.000210 | $21.00 |
| 10,000 | $0.000420 | $42.00 |
These are calculated estimates, not measured invoices. Actual spending depends on token usage, request volume, and the provider's billing rules.
For workflows that ask multiple questions about the same document or application state, batching can also reduce repeated input-token usage. This is particularly useful when a large shared context would otherwise be sent with every individual decision.
How Fast Is the Jev API?
TypeSafe currently publishes a Jev 1.13 response-time range of 70–500 ms. Real end-to-end latency varies by request size, network conditions, workload structure, and whether multiple questions are evaluated together.
What Are the Jev API Limits?
Jev 1.13 supports a 64K-token total context window, with State plus the longest question limited to 32K tokens. Current documented limits also include 1,200 requests per minute, 250,000 tokens per second, up to 255 Choice options, and 2–10 Score levels.
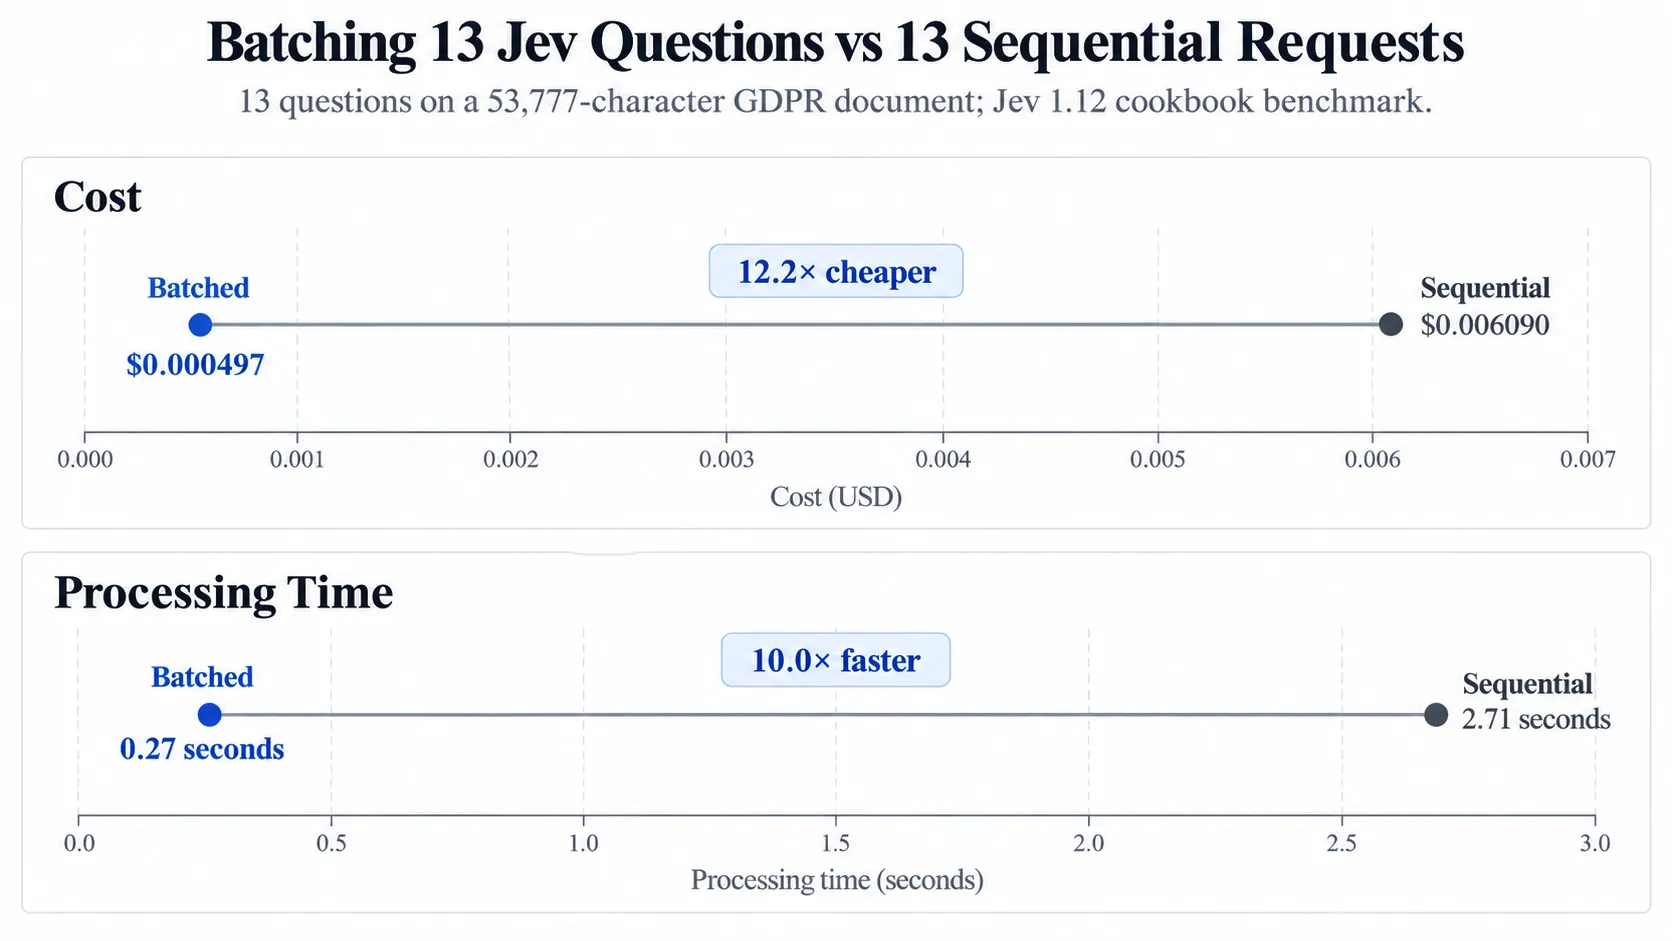
Jev 1.12 Parallel Questions Benchmark: 12.2× Cheaper With Shared Context
Jev can evaluate multiple independent questions against the same shared state, avoiding repeated transmission of large context.
In TypeSafe’s parallel-questions cookbook, run with Jev 1.12, 13 questions were evaluated against a 53,777-character GDPR document.
One batched request:
Cost: $0.000497 Time: 0.27 seconds
Thirteen separate sequential requests:
Cost: $0.006090 Total time: 2.71 seconds
For this workload, batching was 12.2× cheaper and 10.0× faster.
The latency comparison sums sequential calls, so concurrent requests would reduce the wall-clock gap. The cost advantage remains more relevant because separate calls repeatedly send the same large document.
The practical lesson is straightforward:
When several decisions depend on the same context, send that context once and evaluate the questions together.
Jev API Use Cases and Observed Workflow Results
| Test | Reported result | Important limitation |
|---|---|---|
| Agent routing | ~1s vs 4–14s | Third-party observation |
| Coding decisions | 239–430ms | Workload-specific |
| Local Qwen comparison | Both 96.53% accuracy | 144-task sample |
| Claude workflow | 9/10 expected triggers | Trigger success ≠ decision accuracy |
Four independently reported workflows illustrate where Jev can help—and why speed, cost, and decision accuracy must be evaluated separately.
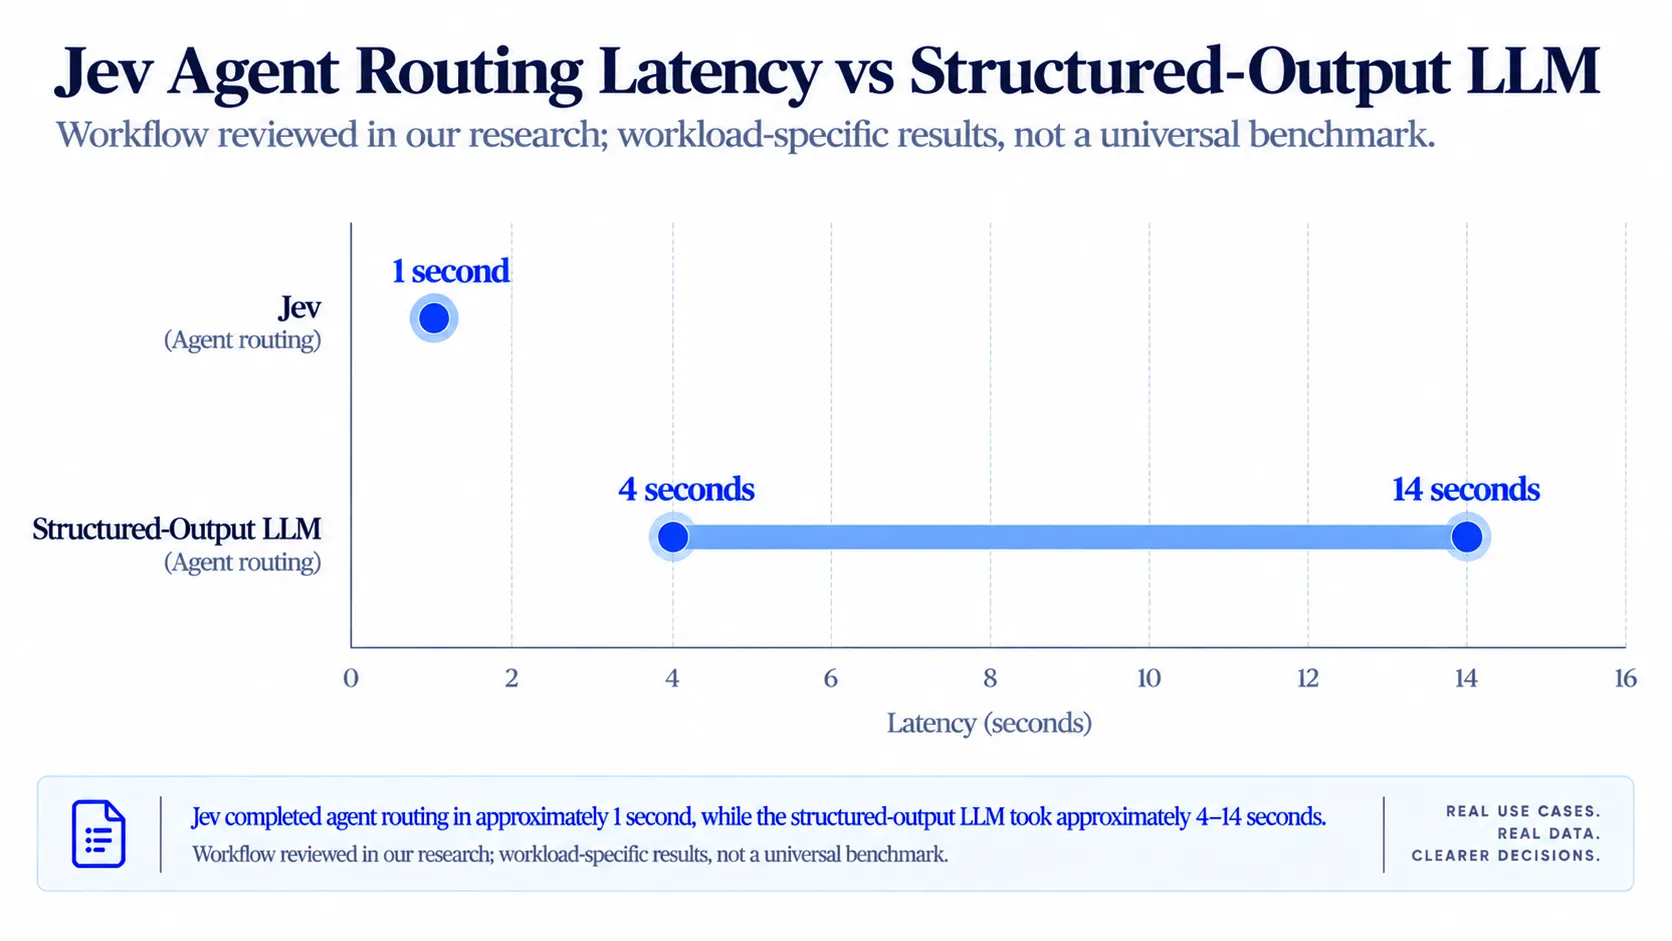
Observed Agent Routing: Jev at ~1 Second vs 4–14 Seconds
In a reported agent-routing workflow, Jev selected agents in approximately 1 second, compared with 4–14 seconds for an LLM using structured output. This suggests that Jev's Choice primitive may reduce routing overhead in multi-agent systems. However, these are third-party observations, not controlled LinkModel benchmarks, and performance depends on task complexity, network conditions, and routing accuracy.
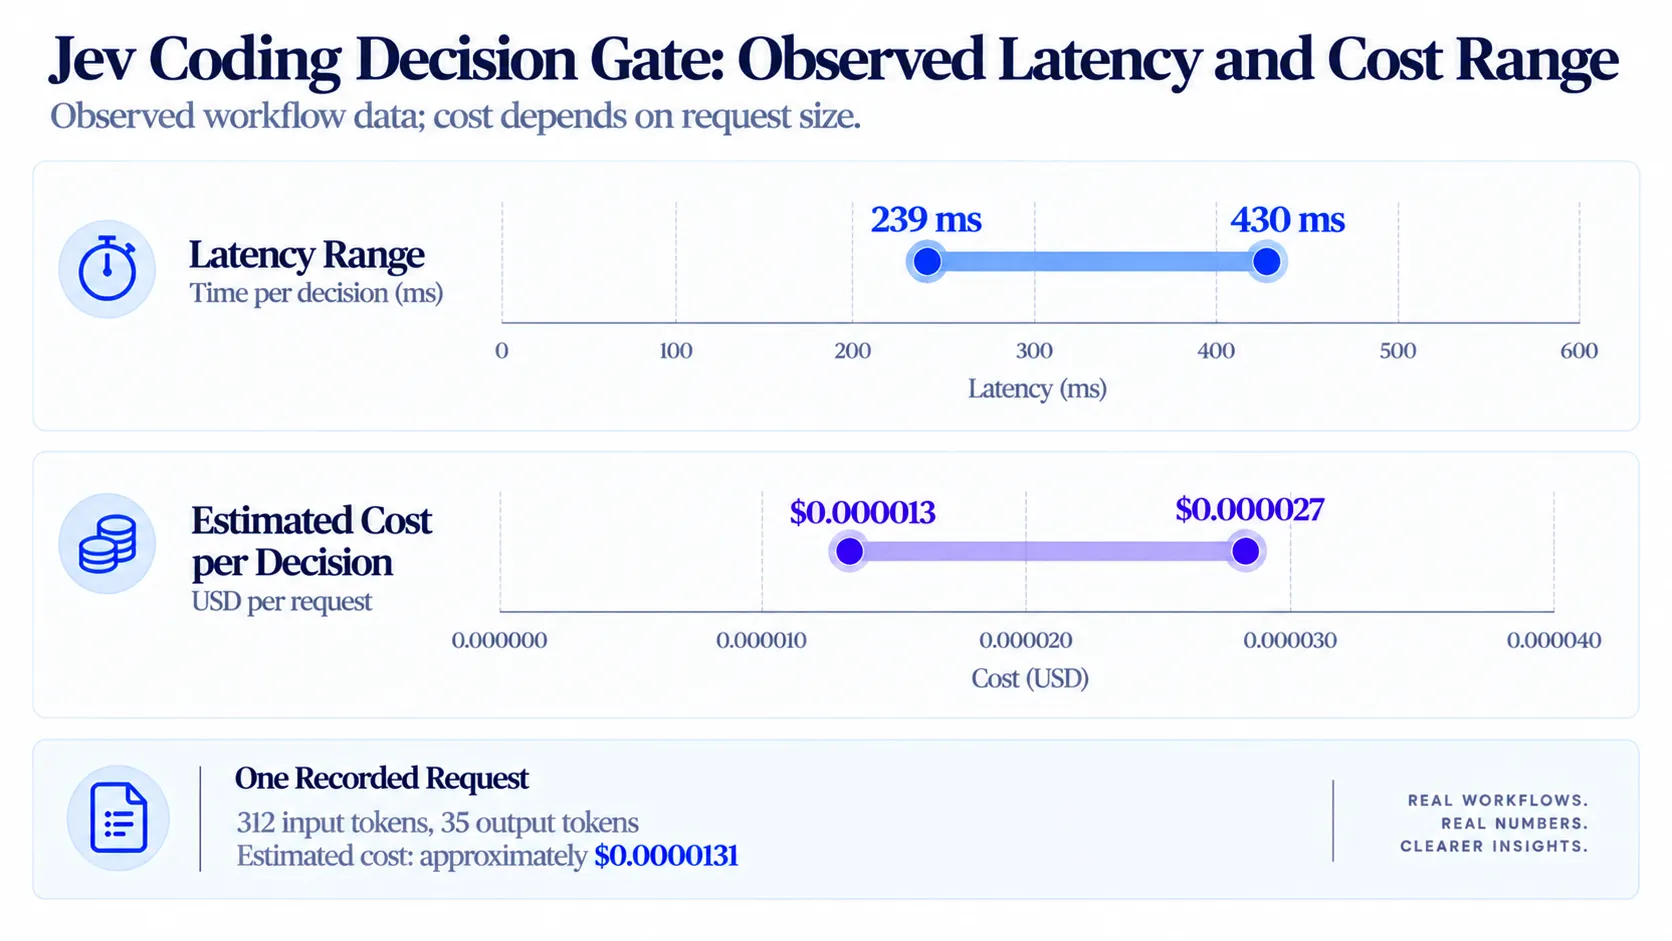
Observed Coding Decision Workflow: 239–430 ms
A reported coding workflow recorded Jev decision latency of 239–430 ms, with estimated costs of $0.000013–$0.000027 per decision. These results suggest that Jev can support inexpensive, repetitive decisions in coding automation. However, the figures reflect specific request sizes and do not establish performance or cost across larger workloads.
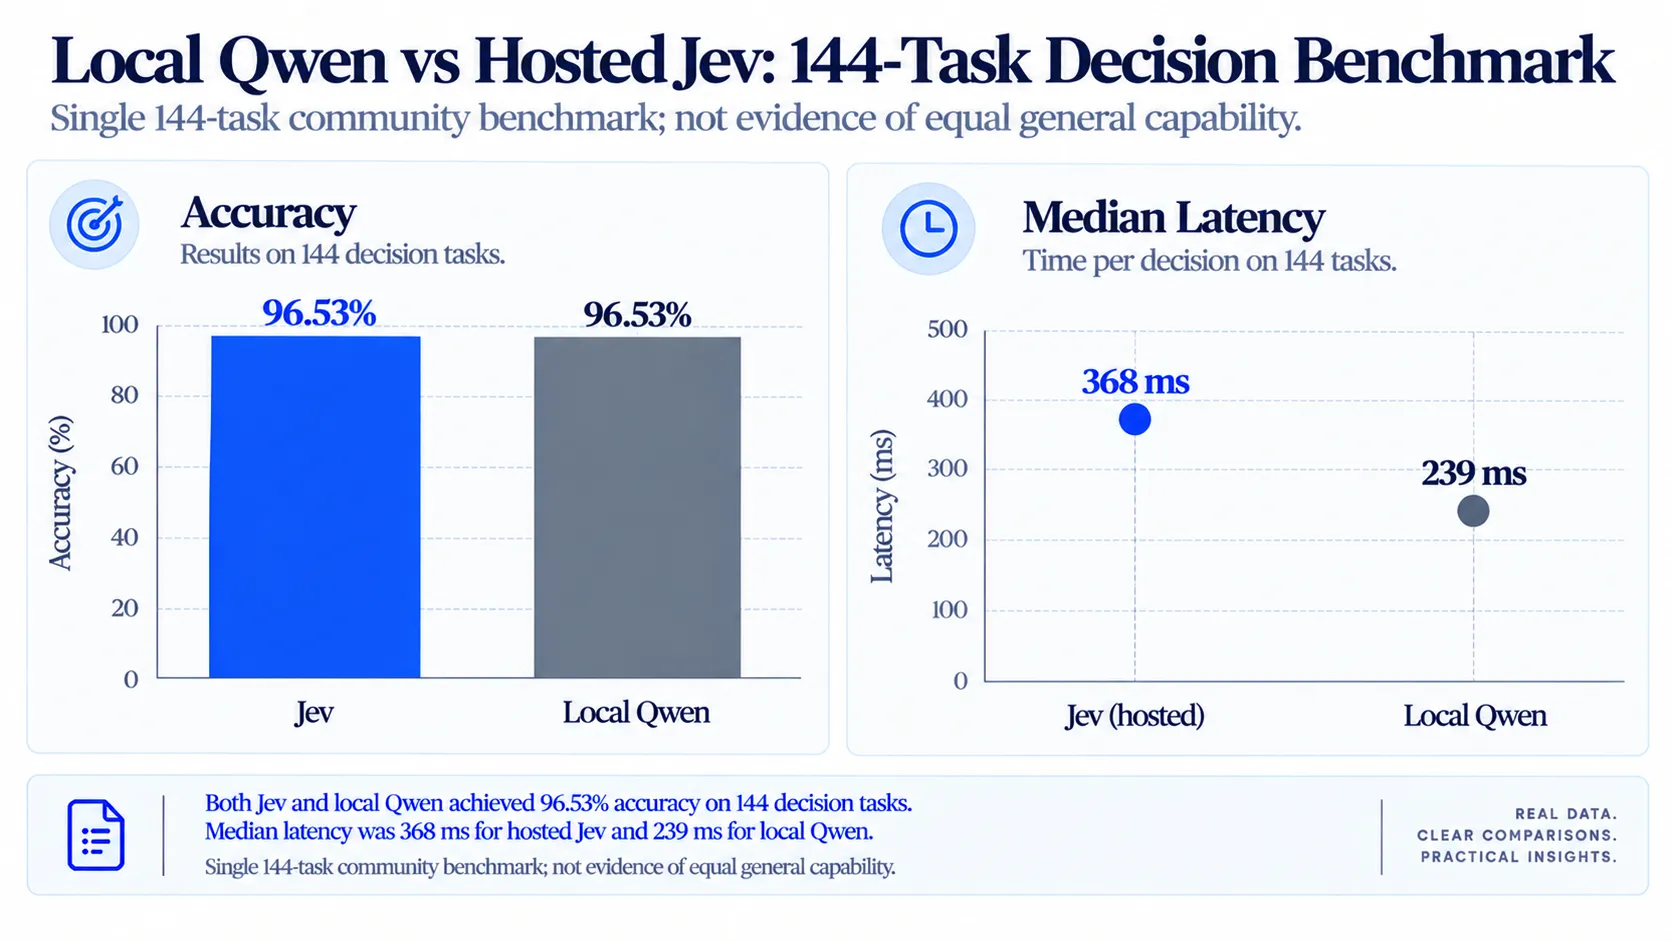
Local Qwen vs Jev: 96.53% Accuracy
In a 144-task comparison, both Jev and a local Qwen implementation achieved 96.53% accuracy. Local Qwen recorded lower median latency (239 ms vs 368 ms), demonstrating that a hosted decision API is not necessarily the fastest option. The limited sample means developers should evaluate deployment costs, privacy, and accuracy on their own tasks.
Claude Decision Workflow: 9/10 Expected Triggers
A Claude Code decision workflow activated in 9 of 10 expected cases, with zero false activations across 10 near-miss cases. However, its first three real decision questions produced mostly incorrect decisions. The result highlights a crucial distinction: reliable workflow triggering does not guarantee accurate decisions. Both should be tested before production deployment.
What Does Jev Confidence Mean? Is 0.90 Confidence 90% Accurate?
No. A Jev confidence value of 0.90 does not automatically mean the decision is 90% likely to be correct. For Choice and Score, confidence describes how concentrated the returned probability distribution is. Whether that confidence corresponds to real-world accuracy must be measured with labeled examples from the target workload.
A Choice where one candidate dominates the probability distribution will have higher confidence than one where several candidates are close.
A useful production pattern is:
| Confidence state | Typical action |
| High | Auto-execute when the consequence is acceptable |
| Medium | Verify, confirm, or send for review |
| Low | Reject, fall back, or escalate |
The production question is therefore not whether confidence looks high, but whether that confidence is calibrated on the target workload.
A stronger process is to create a labeled evaluation set, group predictions by confidence range, measure error rates, and then decide how much automation is acceptable at each threshold.
The business context matters.
A wrong UI route is easily reversed. A wrong financial approval is not.
Confidence thresholds should therefore reflect business risk, not simply model output.
Jev API Limitations and Production Best Practices
The largest Jev production risks are incorrect semantic decisions, weak candidate design, poor calibration, and using a decision model where deterministic code would be safer.
Typed output does not mean the answer is automatically correct. Jev can return a valid Choice that is still the wrong Choice.
Candidate design is especially important. If a router includes only Agent A, Agent B, and Agent C, Jev must choose among them even when none is suitable.
Production schemas should often include escape routes such as:
- Human
- None
- Insufficient evidence
- No suitable option
- Escalate
Jev 1.13 is currently text-only. English is its strongest language. CJK input can be processed, but equal accuracy is not guaranteed, so Chinese, Japanese, and other non-English production workloads need their own labeled benchmarks.
Deterministic operations should also remain deterministic. Arithmetic, date calculation, strict identities, policy constraints, and hard business rules belong in code, not in a probabilistic decision layer.
Finally, production teams should consider pinning jev-1.13.0 after calibration rather than relying indefinitely on jev-latest. A future alias update may preserve the response format while changing probabilities enough to affect routing or threshold behavior.
Jev API vs LLM: When Should You Use Each?
Decision models such as Jev are designed for bounded semantic decisions, while general LLMs remain better suited to open-ended generation, reasoning, planning, and candidate creation. Deterministic calculations and hard business constraints should remain in code.
| Task | Typical best-fit layer |
| Bounded semantic classification | Jev or another decision model |
| Agent routing | Jev or another decision model |
| Risk gating | Jev or deterministic rules, depending on the constraint |
| Ordered semantic scoring | Jev or another decision model |
| Semantic verification | Jev / decision model |
| Writing | General LLM |
| Deep reasoning | General LLM |
| Planning | General LLM |
| Candidate generation | General LLM |
| Deterministic calculation | Code |
A useful production architecture is:
LLM proposes → Jev decides → code executes
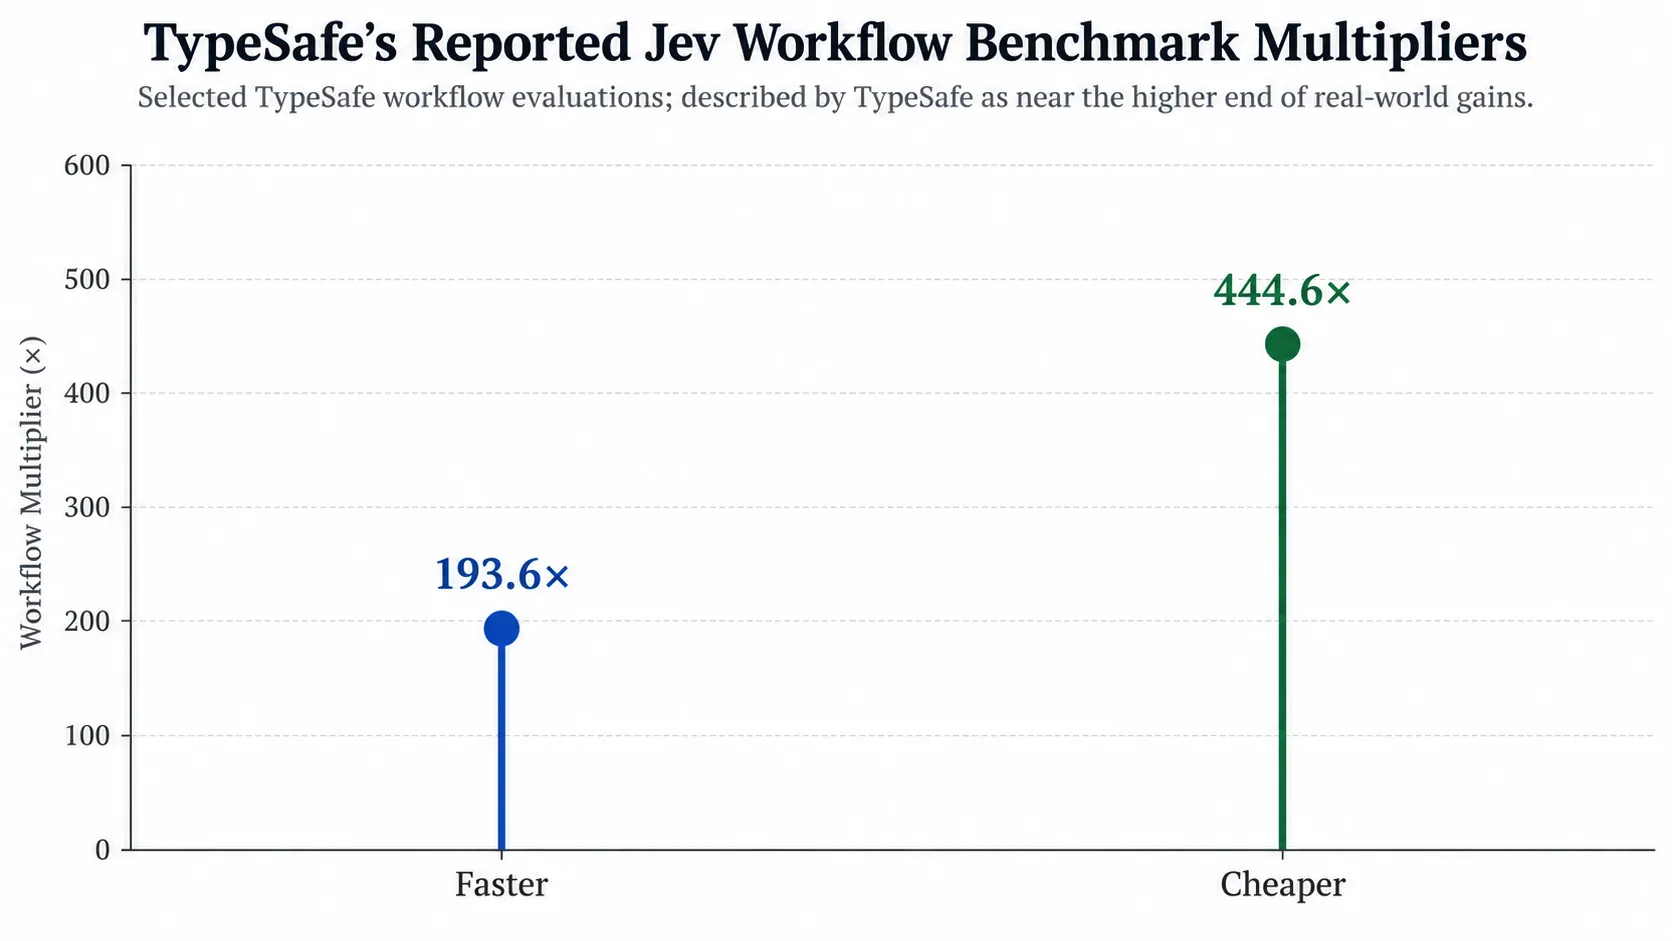
TypeSafe has reported selected workflow evaluations reaching 193.6× faster and 444.6× cheaper, but says these results likely represent the higher end of real-world gains rather than typical Jev performance. TypeSafe also notes that the evaluated workflows were created by members of its own model-capabilities team, so some evaluation bias may remain.
The more useful conclusion is broader:
Decision-shaped workloads can have fundamentally different latency and cost requirements from generation-shaped workloads.
Production teams should benchmark that architectural difference on their own tasks rather than assume one vendor multiplier applies everywhere.
Frequently Asked Questions
How much does the Jev API cost?
Jev 1.13 is listed at $0.042 per million input tokens, with free output tokens. Total spending depends on request volume and input context size.
How do I get a Jev API key?
Sign in to the TypeSafe Console and open the API key settings. Keep the key server-side and use it as a bearer token when calling the API.
What is the Jev API endpoint?
The direct endpoint is https://api.typesafe.ai/v1/systemone. Send POST requests with model, state, and questions in the JSON body.
Is the Jev API free?
Free output tokens do not mean free API usage. Input tokens are billed according to the provider's applicable rates. Check TypeSafe for any current promotional credits.
Can I use the Jev API with Python?
Yes. You can use Python's requests library or the TypeSafe SDK to submit typed questions and read structured responses.
Is Jev an LLM?
TypeSafe describes Jev as a System One Model optimized for typed probabilistic decisions rather than open-ended text generation.
Can Jev replace GPT or Claude?
Not for general-purpose writing, planning, or complex generation. Jev is designed for narrower decisions such as routing, classification, verification, and scoring.
Does Jev confidence guarantee accuracy?
No. Confidence reflects the model's reported uncertainty, not guaranteed correctness. Decision thresholds should be validated against labeled examples from the intended workload.
Conclusion
Jev API is a practical option for applications that need fast, structured decisions rather than another generated response. With Noul, Choice, and Score, developers can build classification, routing, verification, and scoring workflows while keeping input-token costs predictable. The strongest architecture is often a combination of specialized decision models, general-purpose LLMs, and deterministic application logic. For the generation and reasoning layer, LinkModel offers a unified way to explore supported AI models and compare API pricing. Before deploying a Jev-based workflow, test decision accuracy, confidence calibration, latency, and total cost on your own workload.